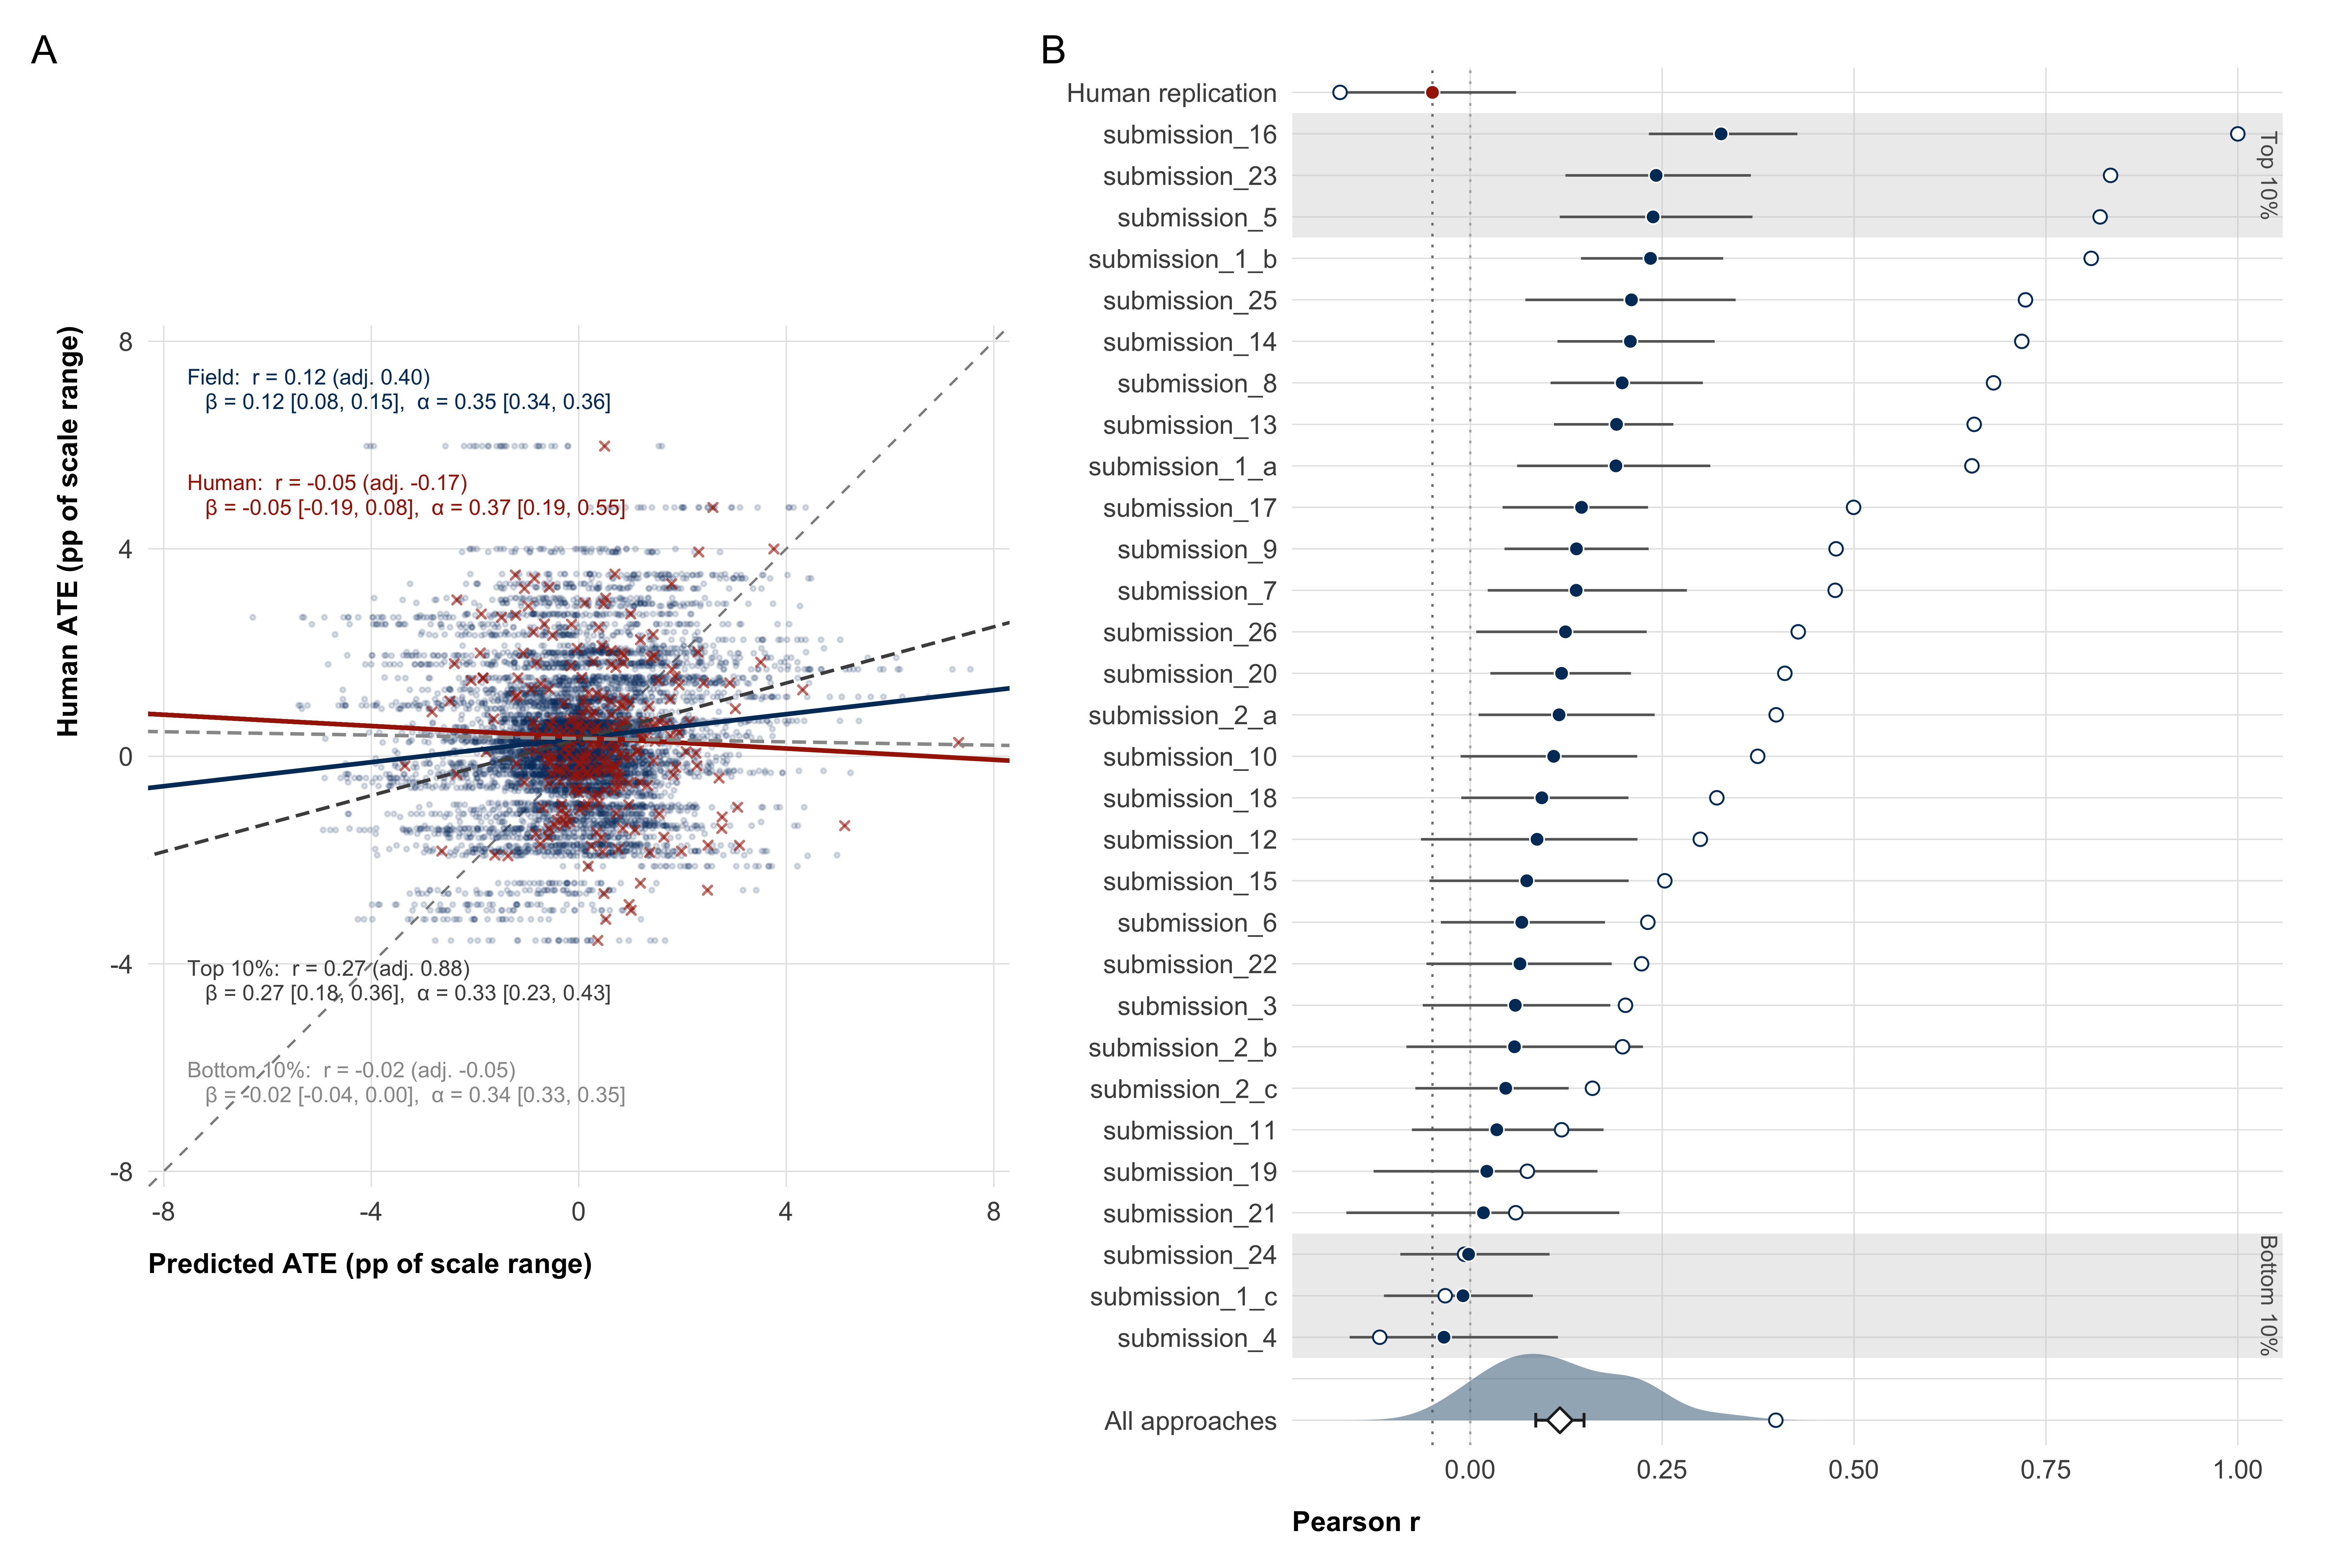
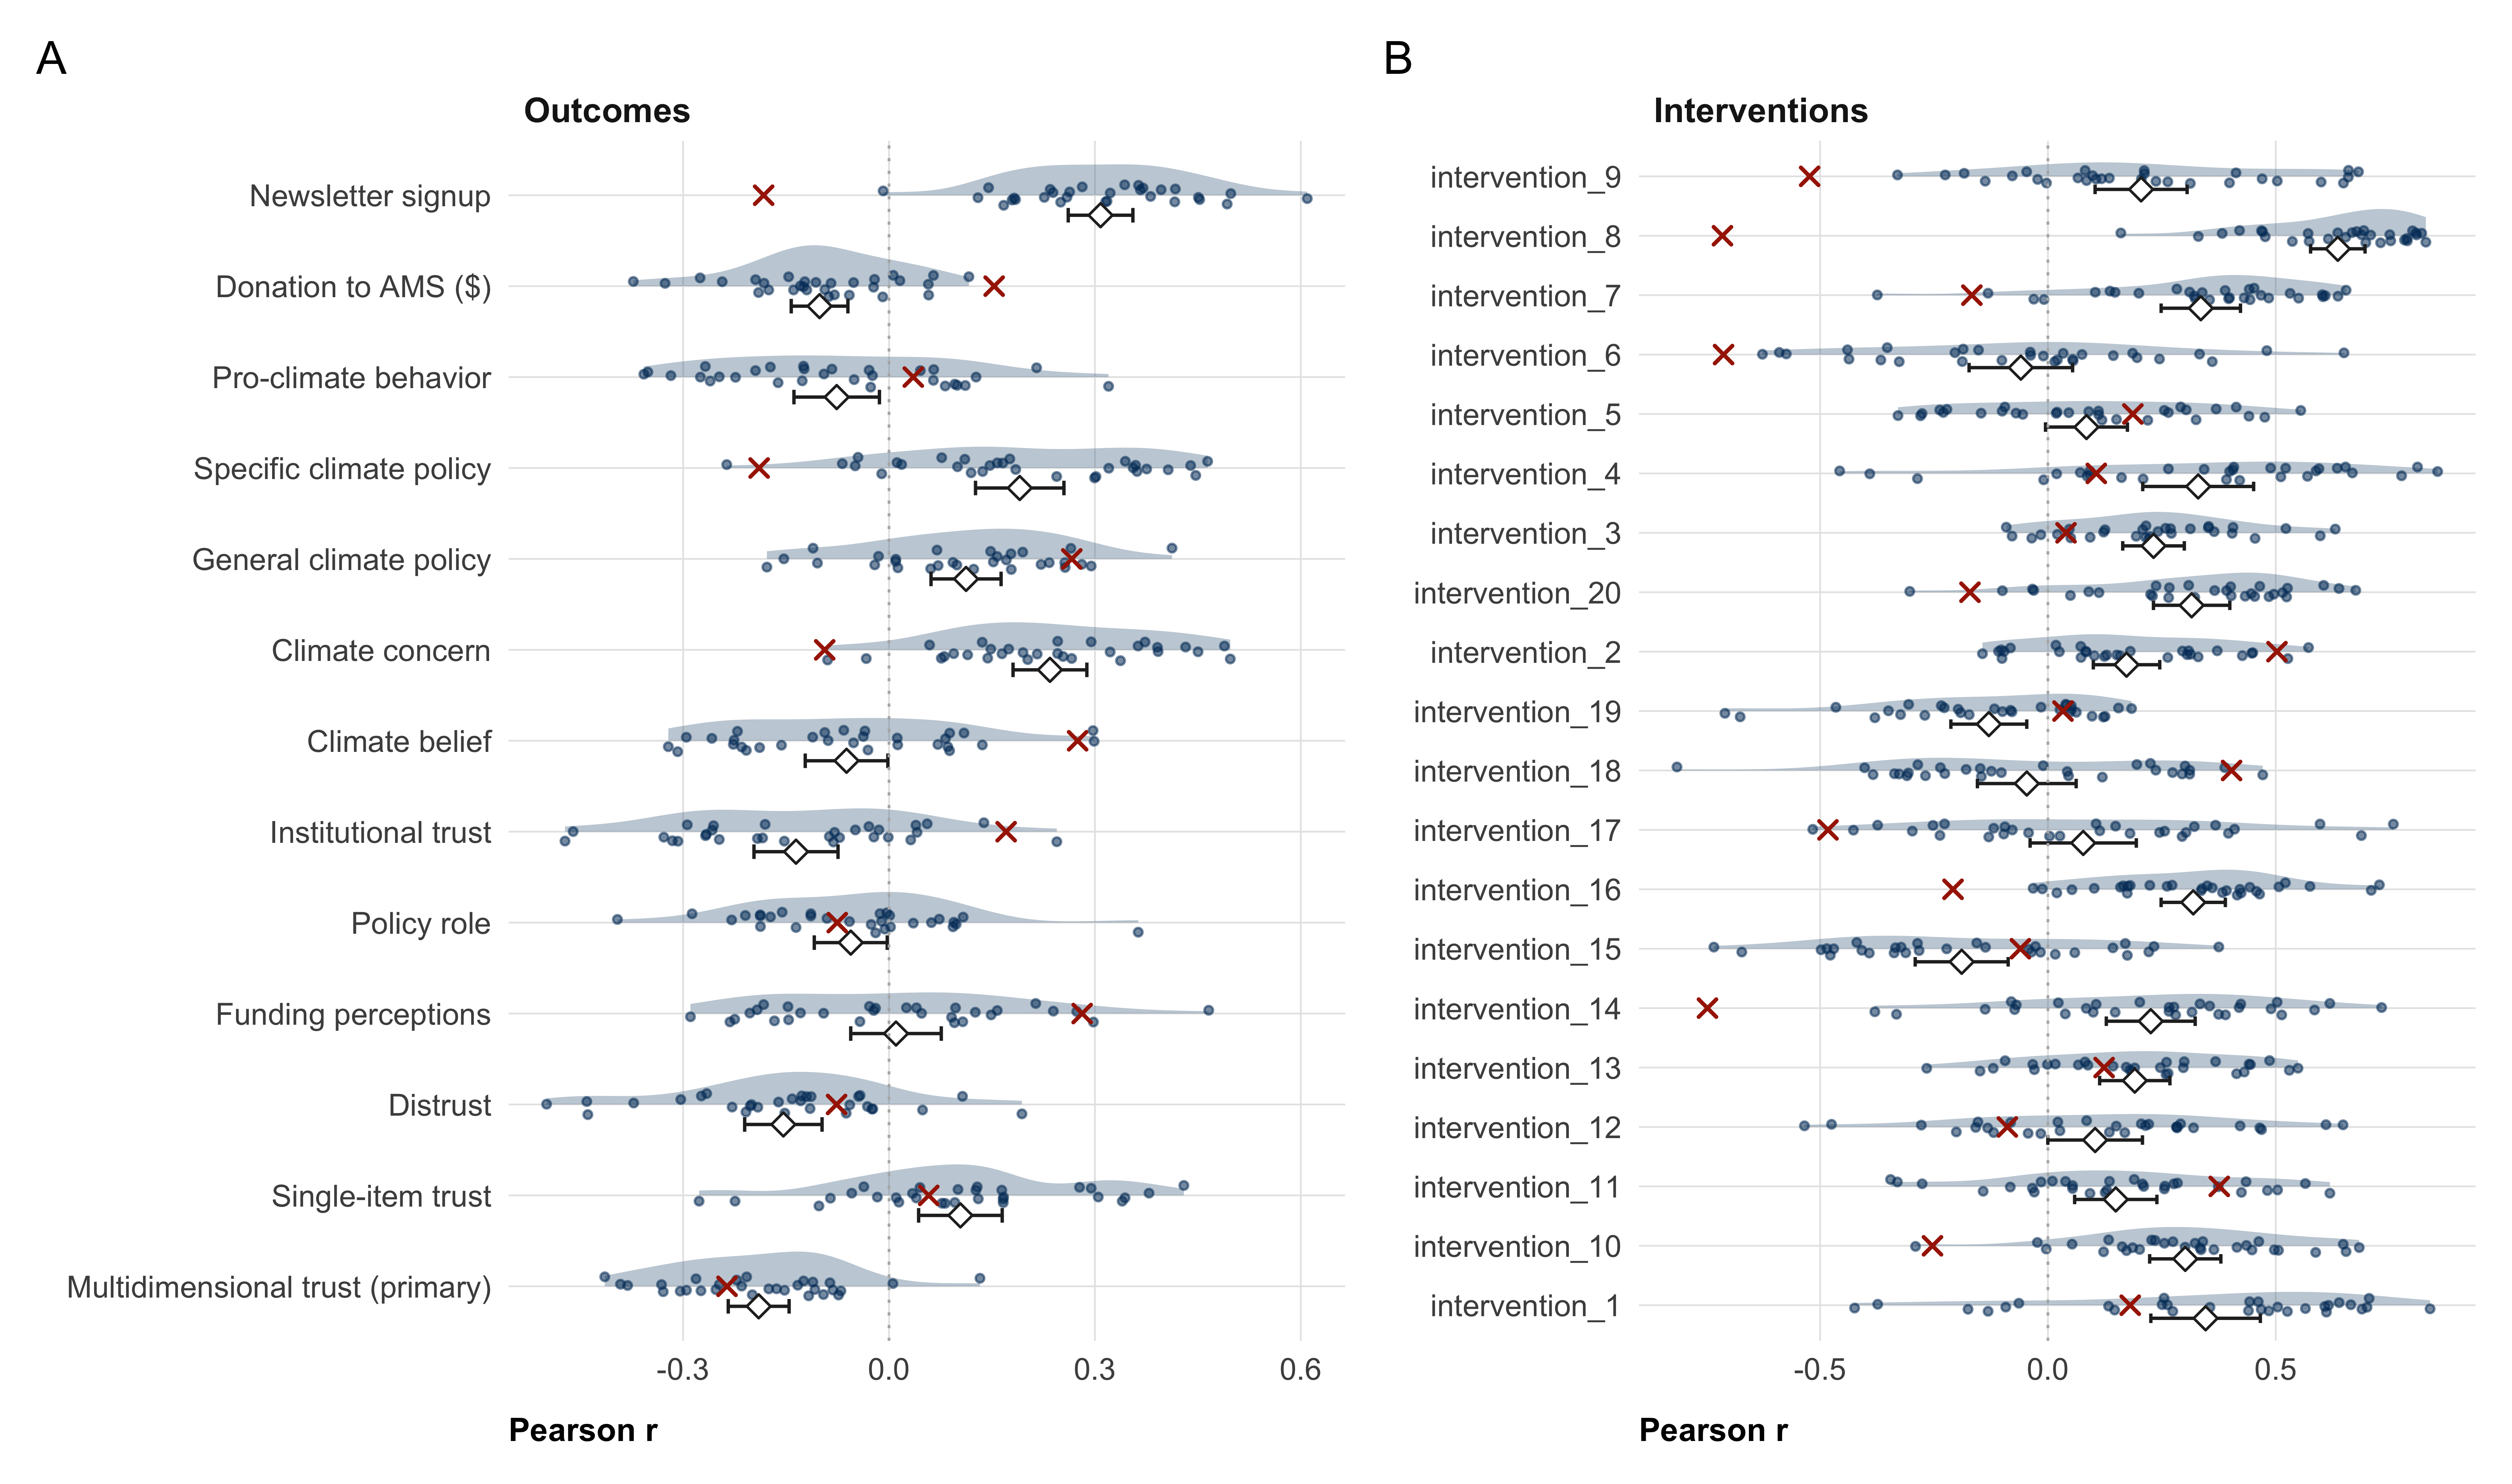
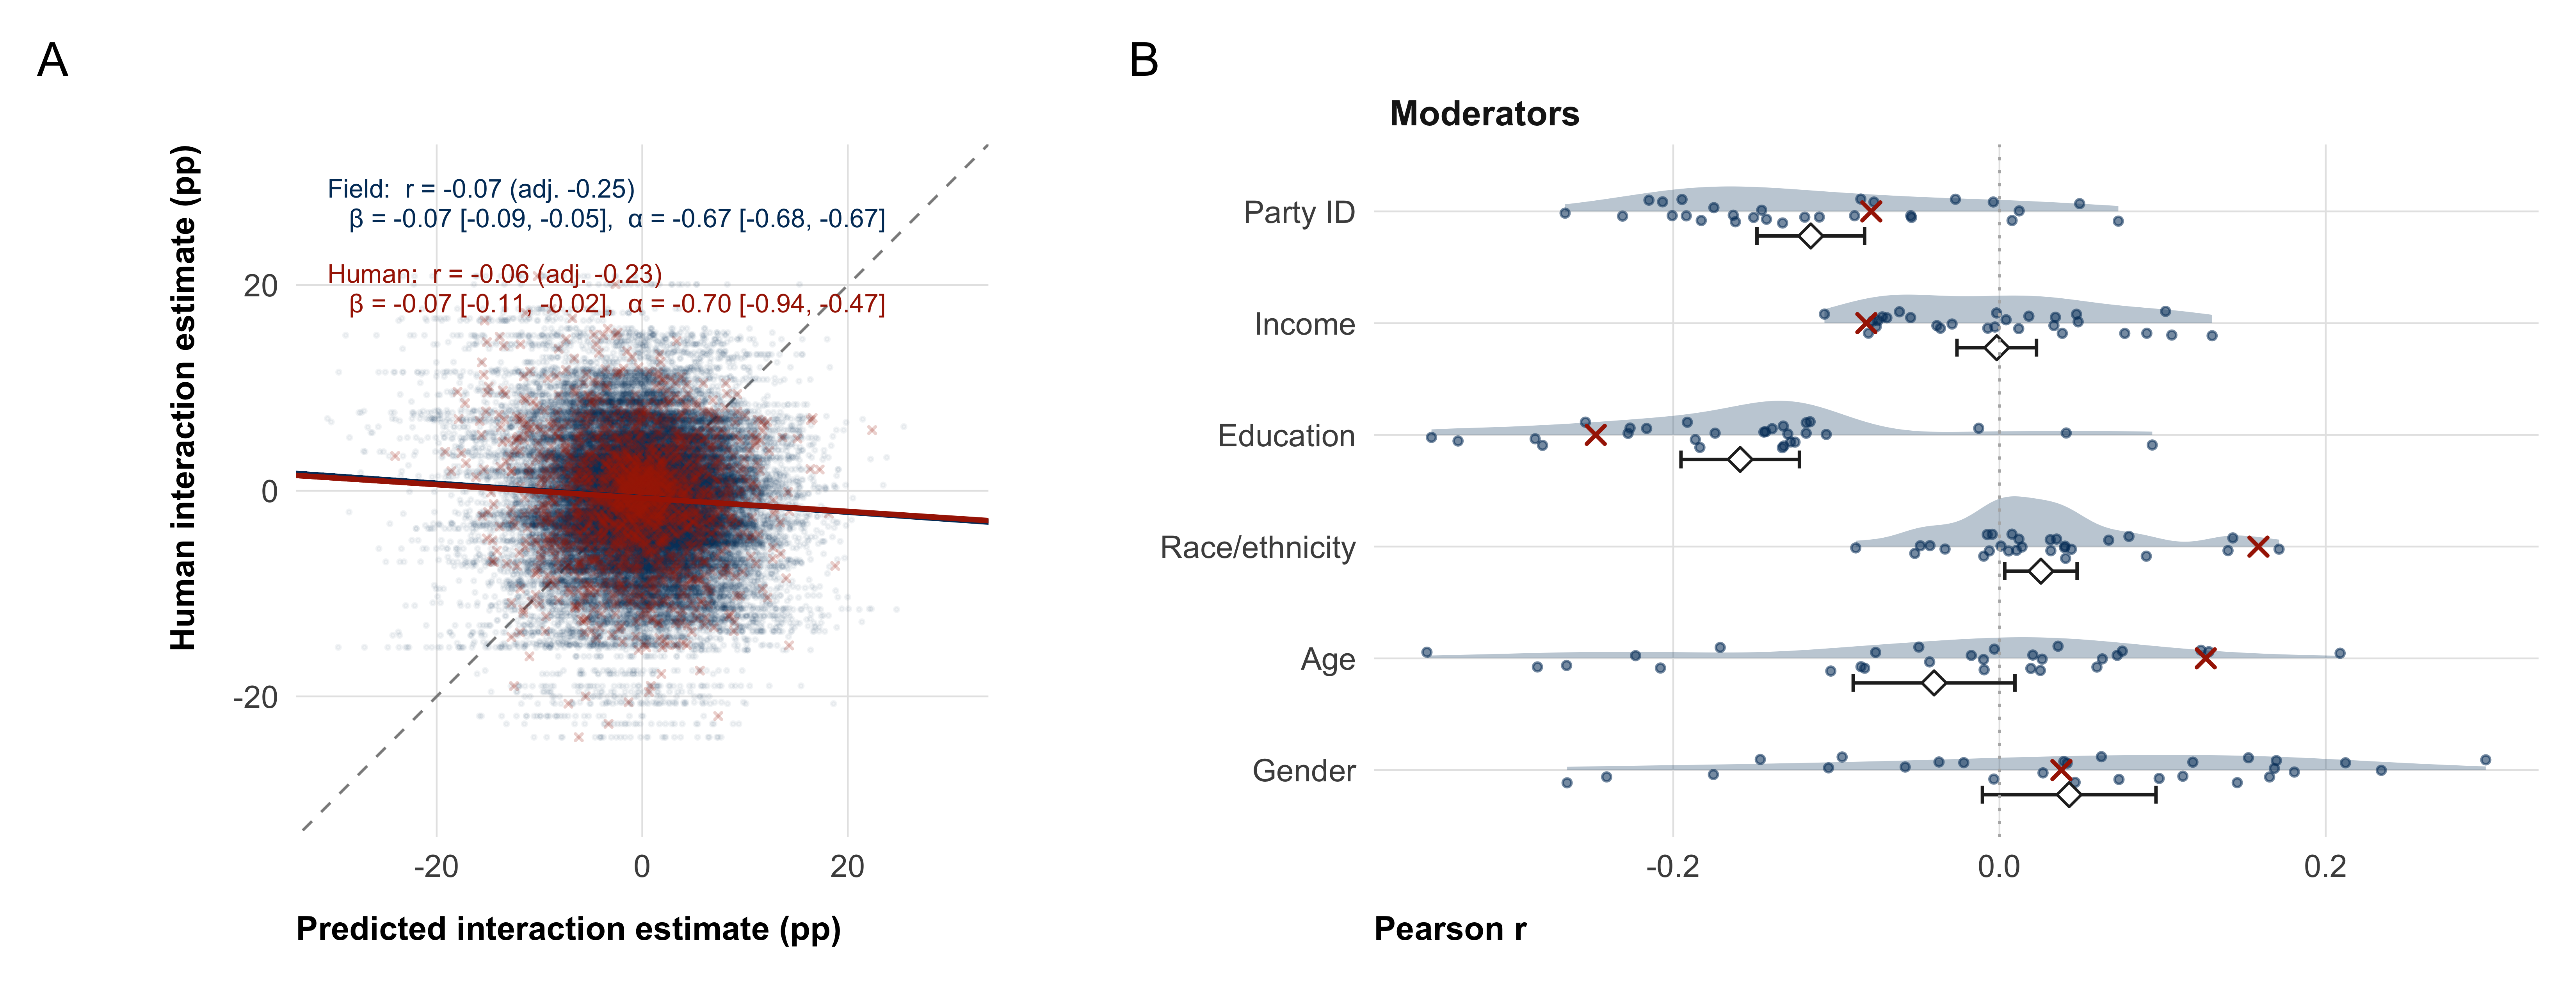
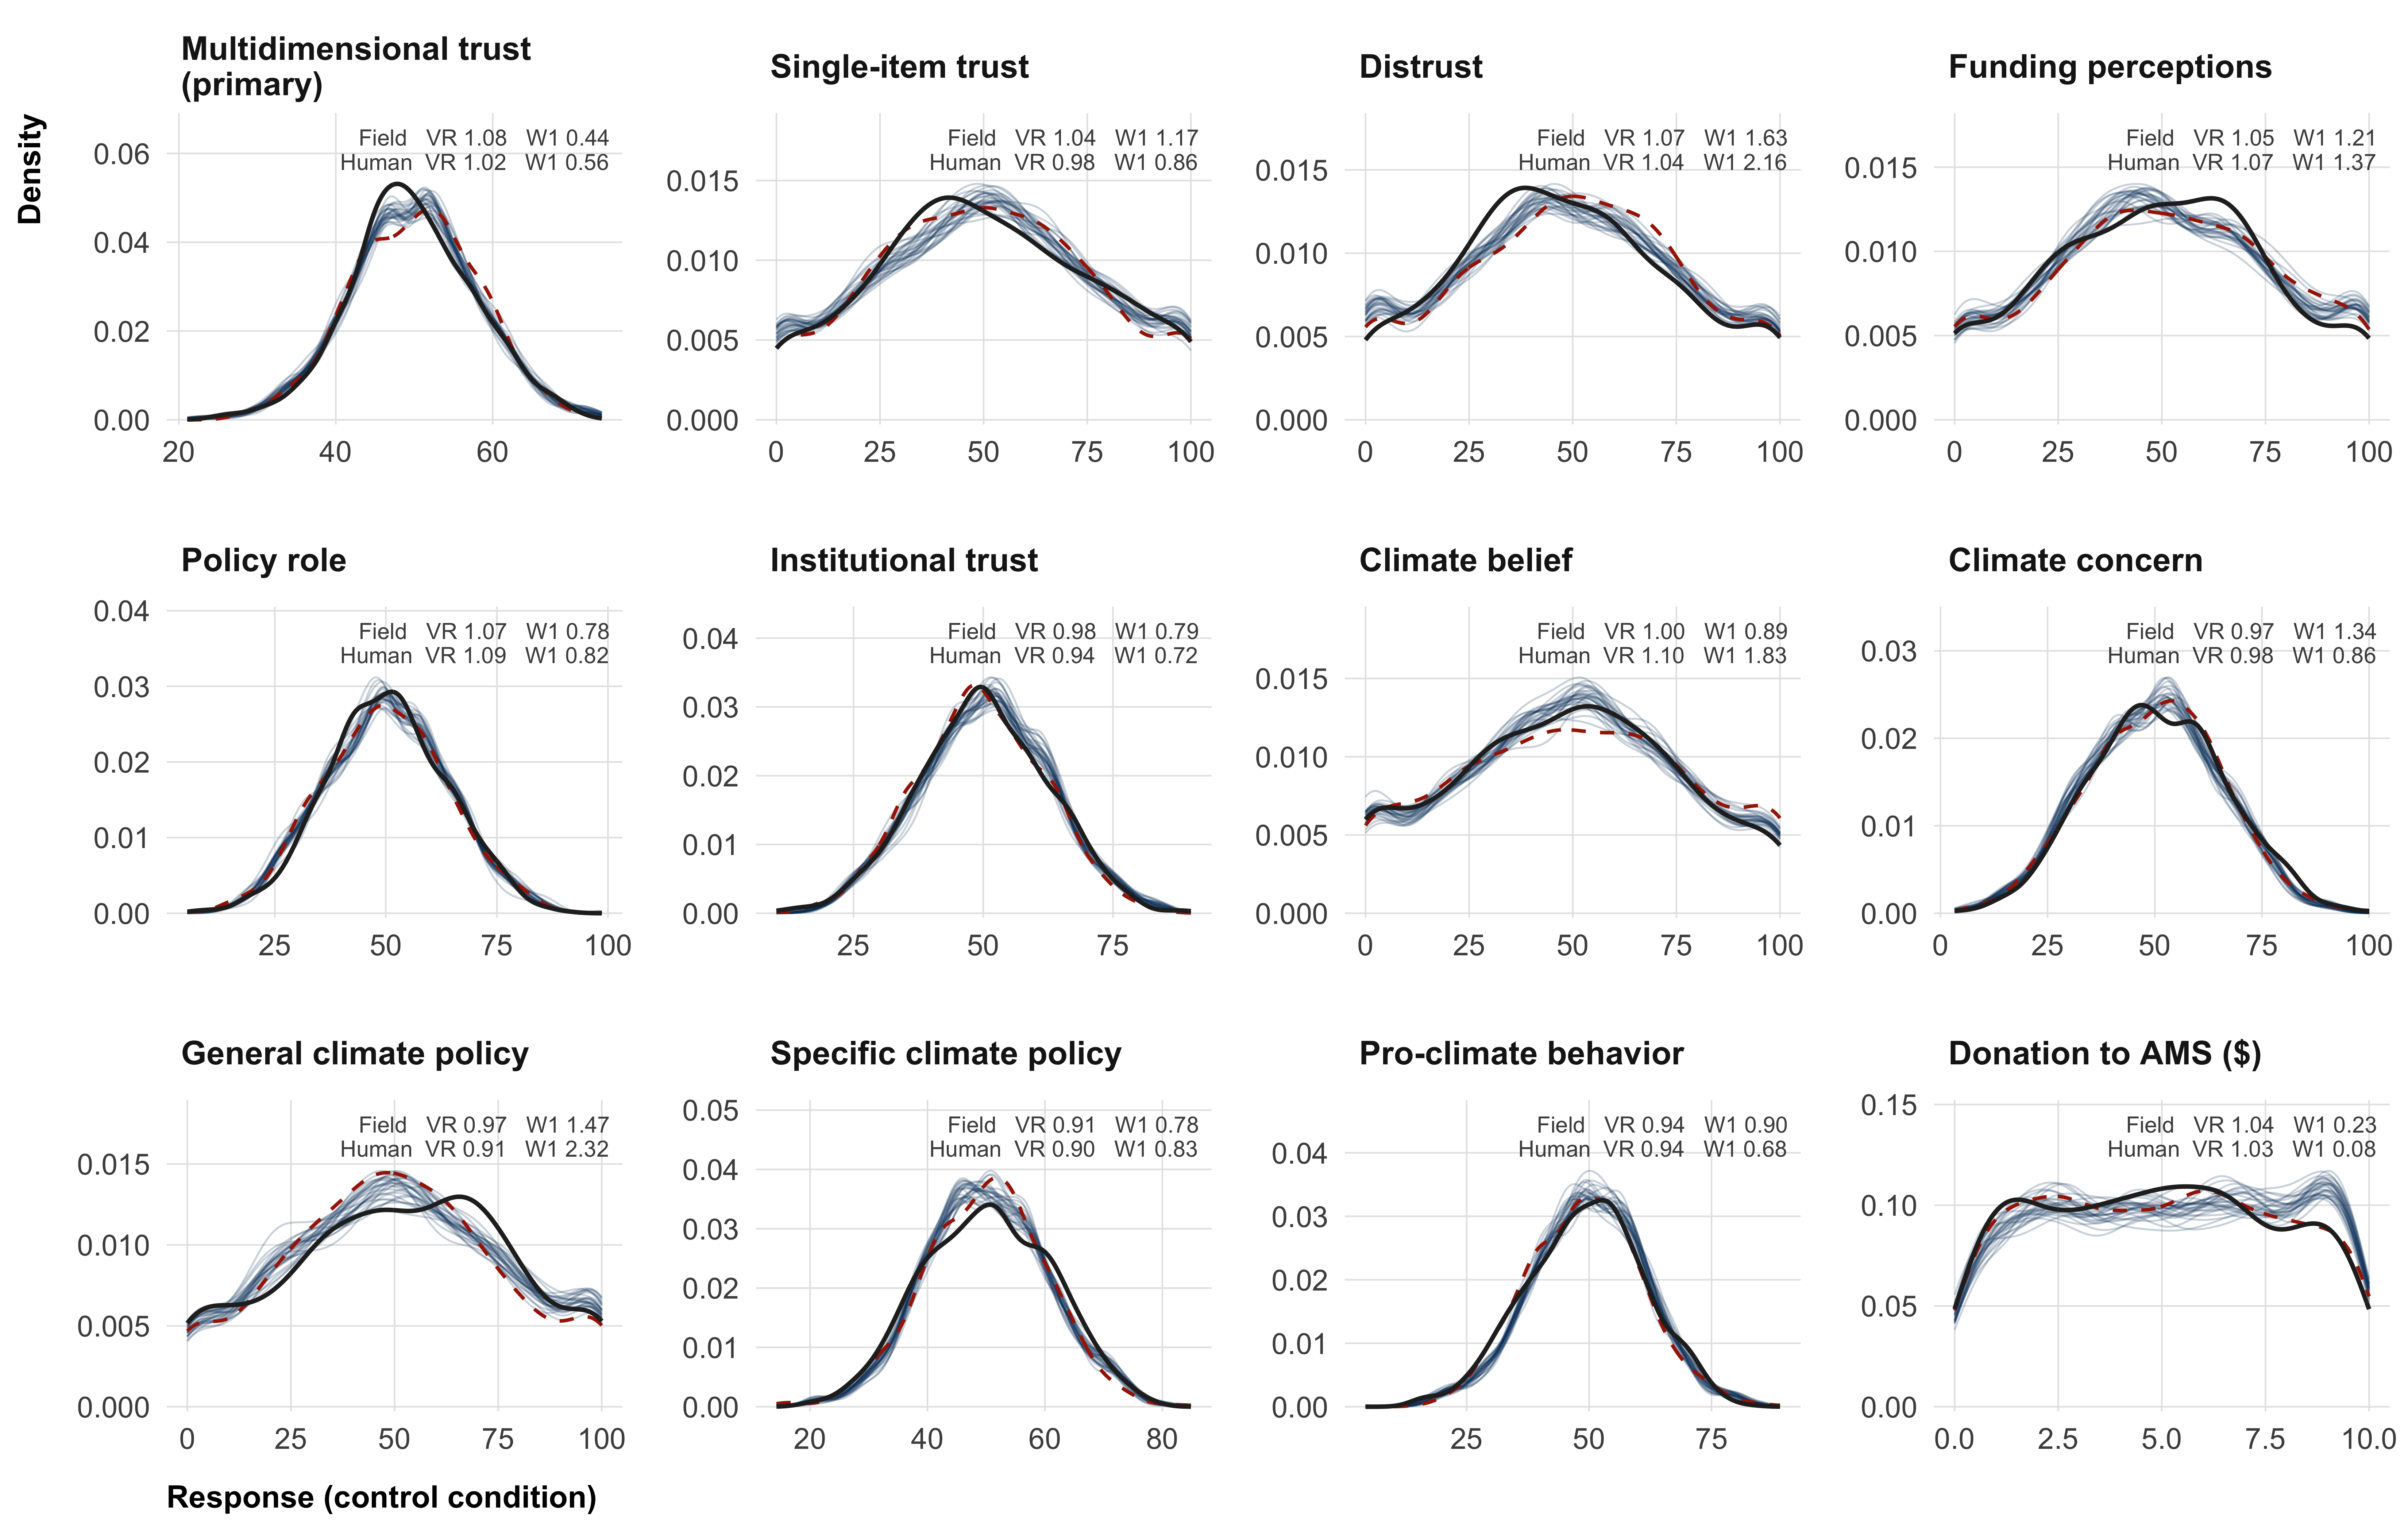
---
title: "The Silicon Sample Benchmark: A multi-team preregistration for predicting behavioral-experiment effects"
abstract: |
This is the preregistration for the **Silicon Sample Benchmark**, a multi-team prediction benchmark. We invite independent research teams to predict the results of a novel behavioral megastudy (16 message interventions to increase trust in climate scientists, 13 preregistered outcomes, a representative U.S. sample of ~18,000) with any AI-based approach they choose, from behavioral clones to group-level simulation to direct effect forecasting. At the time of writing, human data collection is complete. None of these data have been shared, published, or made accessible to any prospective team, and no team will be granted access before the prediction lock. Before any human data are released, every team registers its predictions using a standardized method-registration form and deposits its predictions on Zenodo. At the time of this preregistration, 33 teams have registered to participate in response to our invitation, and no submissions have been received.
date: "2026-08-15"
format:
html:
code-fold: true
toc: true
toc-depth: 4
# PDF disabled for now to speed up iteration — re-enable for the final render.
# pdf:
# toc: true
# toc-depth: 5
# include-before-body:
# text: |
# \clearpage
# colorlinks: true
# tbl-colwidths: true
# header-includes:
# - \usepackage{float}
# - \floatplacement{figure}{H}
# - \floatplacement{table}{H}
# - \usepackage{listings}
# - \lstset{breaklines=true, basicstyle=\small\ttfamily}
execute:
echo: true
warning: false
message: false
fig-width: 8
fig-height: 5
fig-dpi: 300
---
```{r}
#| label: setup
#| output: false
# packages
library(tidyverse)
library(sandwich)
library(lmtest)
library(marginaleffects)
library(broom)
library(MetBrewer)
library(gghalves)
library(patchwork)
library(gt)
library(tinytable)
library(here)

# custom functions (reused unchanged from the original preregistration)
source(here("R/functions/statistics.R"))
source(here("R/functions/plots.R"))
source(here("R/functions/tables.R"))
source(here("R/functions/reporting.R"))

# simulated (random) placeholder data
human_data     <- readRDS(here("data/simulation_preregistration/human_data_preregistration.rds"))
llm_data_teams <- readRDS(here("data/simulation_preregistration/llm_data_preregistration_teams.rds"))

# TRUE while this document renders on the simulated placeholder data. At
# scoring, the real-data loader replaces the placeholder loader above and this
# flag flips to FALSE, which switches off the placeholder-only condition
# fallback below — the registered pipeline has a single path.
placeholder <- TRUE

# Restrict the human data to the scored conditions (the 16 non-interactive
# interventions + control) BEFORE any model is fit. The real cleaned human
# data will additionally contain the three chatbot arms and the value-
# similarity arm, which no submission predicts; fitting the human models on
# those arms would put the human side's BH adjustment over a different test
# family than the submissions'.
#
# The scored set comes from the canonical intervention list
# (data/interventions.csv, titles trimmed, the four interactive arms
# excluded) — never from a submission's own condition labels, so a mislabeled
# or missing condition in a submission can neither widen nor shrink the
# scoring universe.
canonical_interventions <- read_csv(here("data/interventions.csv"),
                                    show_col_types = FALSE) |>
  filter(str_trim(tag) != "LLM-chatbot", str_trim(title) != "Value similarity") |>
  pull(title) |> str_trim() |> unique()

scored_conditions <- c("control", canonical_interventions)

# Placeholder-only fallback: the simulation uses generic intervention_N labels
# that are not in the canonical list, so the scored set is taken from the
# conditions the simulation generates (all scorable by construction), which
# keeps this document renderable. Inactive at scoring.
if (placeholder) {
  scored_conditions <- levels(droplevels(factor(llm_data_teams$condition)))
}

human_data <- human_data |>
  filter(condition %in% scored_conditions) |>
  mutate(condition = droplevels(condition))

# Every estimation function takes the first factor level of `condition` as the
# reference, so the control condition must come first before any model is fit.
stopifnot(levels(human_data$condition)[1] == "control")

# Same preregistered random split of the human sample as in the original
# preregistration. Human 1 is the reference half all submissions are scored
# against; Human 2 is the human replication reference.
set.seed(42)
split_ids    <- sample(unique(human_data$id), size = floor(length(unique(human_data$id)) / 2))
human_data_1 <- human_data |> filter(id %in% split_ids)
human_data_2 <- human_data |> filter(!id %in% split_ids)
```
::: {.callout-note}
**Status at registration (August 15, 2026).** In response to our invitation, **33 teams** have registered to participate. **No submissions have been received at this stage** — the prediction lock, by which every team must have deposited its predictions, is August 31, 2026.
:::
::: {.callout-important}
**This is the preregistration for the benchmark.** It supersedes the project's earlier preregistration for a single-team design ([v1](preregistration.qmd)). The section [*About this preregistration*](#sec-about) explains why this second preregistration exists, what it keeps from v1, and what it changes.
The benchmark's design (motivation, rules, the three tiers, the full method-registration form, the disclosure policy, scoring, and the timeline) is also described in the [call for participation](index.html). To avoid redundancy, this preregistration document only summarizes the participatory design laid out in the call.
All datasets used for demonstration here are simulated random noise with the correct structure.
:::
## Motivation {#sec-motivation}
Whether large language models (LLMs) can predict how human participants behave in surveys and experiments is a consequential open question in social sciences. The evidence so far is mixed, and has methodological issues: Most existing evaluations target experiments that were already published, and plausibly in the models’ training data. Even in cases where the data from these published experiments is outside of the LLMs' training data, reported success rates may still be biased by researcher degrees of freedom. The analytical procedure, evaluation metrics, models, and prompts researchers use impact their findings considerably [@cumminsThreatAnalyticFlexibility2025b]. A credible evaluation of LLMs' potential for predicting human behavior in social science research requires new data and preregistered methods.
To address these issues, we aim to provide a preregistered, multi-team prediction benchmark, the *Silicon Sample Benchmark*. Independent teams predict the same novel megastudy (N ≈ 18,000) with any AI-based approach, and all approaches are evaluated using the same preregistered procedures. The target data is novel, and none of the interventions has been tested in their exact form before. All teams' predictions are deposited and time-stamped before any human data are released. The full rationale, rules, and incentives for participating teams are laid out in the [call for participation](index.html).
The benchmark scores the 16 non-interactive text interventions of the megastudy^[The original experiment contains 20 intervention conditions plus a shared control. The benchmark scores only the 16 non-interactive text interventions. The four left out are the three interactive LLM-chatbot arms and the "Value similarity" quiz, all of which depend on a live back-and-forth that would substantially complicate the simulation task.], across self-reported attitudes (e.g., trust in climate scientists, support for funding of climate science) and behavioral measures (a donation to a scientific organization, a newsletter sign-up).
The goal of the benchmark is *not* to crown a single champion team. Instead, we aim to map the current design space of synthetic sample approaches and to evaluate, as a field, how well they predict human behavior. This benchmark study will provide a catalogue---a structured, comparable description of how research teams currently approach AI prediction of behavioral experiments (open- vs. closed-weight models, persona sources, administration protocols, fine-tuning, in-context learning), compiled from the method-registration forms (see [*Finding 3*](#sec-finding-3)). We will evaluate approaches on a set of metrics, from directional agreement to calibration, plus distributional fidelity and stereotyping diagnostics (all specified in full under [*Analysis plan*](#sec-analysis-plan), below). We expect different approaches to win on different metrics.
@tbl-interventions gives an overview of the 16 interventions, grouped by their content. All are short text messages (e.g., an article, an interview excerpt, corrected statistics, a portrait) shown once before the outcome battery. Together with the shared control condition they make up the 17 conditions every submission needs to cover.
```{r}
#| label: tbl-interventions
#| tbl-cap: "The 16 text-based interventions scored in the benchmark, grouped by the broad angle each takes on trust in climate scientists. The **Code name** column gives the internal condition identifier used in the raw survey files (`survey.qsf` / `survey.json`) in the submission template. Each intervention has exactly one code name; where intervention-author teams were combined, the code name is a semicolon-joined list, and the semicolons are part of the name (see `survey/condition_codenames.csv` in the benchmark repository). The original megastudy also fields three interactive LLM-chatbot arms and a 'Value similarity' quiz; these four interventions are interactive and excluded from the simulation benchmark, leaving 16 interventions plus a shared control condition (17 conditions in total)."
interventions <- read_csv(here("data/interventions.csv"), show_col_types = FALSE)

tag_order <- c(
  "Collaboration and peer-review",
  "Scientific methods and results",
  "Applications and impact",
  "Others' endorsement",
  "Values",
  "Other"
)

# Same table layout as v1: category headers inserted
# as bold full-width rows, with a running intervention number.
intervention_table_data <- interventions |>
  mutate(across(c(title, summary, tag, code_name), str_trim)) |>
  filter(tag != "LLM-chatbot", title != "Value similarity") |>
  mutate(tag = factor(tag, levels = tag_order)) |>
  arrange(tag, title) |>
  mutate(number = as.character(row_number())) |>
  # internal condition code names exactly as in the raw survey files
  # (survey.qsf / survey.json); semicolon-joined names are a
  # single identifier — semicolons are part of the name, never split.
  mutate(codename = code_name) |>
  group_by(tag) |>
  group_modify(~ bind_rows(
    tibble(title = as.character(.y$tag), codename = "", summary = ""),
    .x
  )) |>
  ungroup() |>
  mutate(` ` = ifelse(title %in% levels(tag), "", number)) |>
  select(` `, title, codename, summary) |>
  rename(`Intervention Title` = title, `Code name` = codename, Summary = summary)

# identify header rows
header_rows <- which(intervention_table_data$` ` == "")

intervention_table_data |>
  tt(width = c(0.04, 0.19, 0.17, 0.60)) |>
  format_tt(escape = TRUE) |>
  style_tt(align = "l", alignv = "t") |>
  style_tt(i = 0, bold = TRUE) |>
  style_tt(i = header_rows, bold = TRUE, j = 2, colspan = 3) |>
  style_tt(j = 3, monospace = TRUE) |>
  style_tt(fontsize = 0.85)
```
@tbl-outcomes summarizes the 13 preregistered outcomes every submission predicts: the primary trust composite, ten further attitude measures (all 0–100 sliders), and two behavioral measures. Multi-item scales enter the analysis as the mean of their items. The exact item wordings and response scales are provided in a codebook in the [submission template repository](https://github.com/janpfander/silicon-sample-submission).
```{r}
#| label: tbl-outcomes
#| tbl-cap: "The 13 preregistered outcomes. Variable names, item counts, example items, and response scales follow the codebook (`codebook.csv` in the benchmark submission template repository), which lists every underlying item in full. Multi-item scales are analyzed as the mean of their items."
tribble(
  ~Outcome, ~Variable, ~Items, ~`Example item`, ~Scale,
  "Multidimensional trust (primary)", "trust_multidimensional", "12",
    "How incompetent or competent are most climate scientists? (four subscales: competence, integrity, benevolence, openness; three items each)",
    "0–100",
  "Single-item trust", "trust_post", "1",
    "How much do you trust climate scientists?", "0–100",
  "Distrust", "distrust_post", "1",
    "How much do you distrust climate scientists?", "0–100",
  "Funding perceptions", "funding_perceptions", "1",
    "Do you think the federal government is spending too much, too little or about the right amount of money on climate change research? (reverse-coded: higher = supports more funding)",
    "0–100",
  "Policy role", "policy_role_mean", "4",
    "Climate scientists should work closely with policy makers to integrate scientific results into policy-making.", "0–100",
  "Institutional trust", "inst_trust_mean", "5",
    "How much do you trust the following institutions? — Environmental Protection Agency (EPA)", "0–100",
  "Climate belief", "belief_post", "1",
    "How accurate do you think this statement is? \"Human activities are causing climate change.\"", "0–100",
  "Climate concern", "concern_mean", "3",
    "How concerned are you about climate change?", "0–100",
  "General climate policy", "policy_general", "1",
    "How much do you oppose or support: \"The U.S. government should do more to reduce global warming\"", "0–100",
  "Specific climate policy", "policy_specific_mean", "7",
    "How much do you support or oppose: Raising taxes on fossil fuels (e.g., gas, oil, coal)", "0–100",
  "Pro-climate behavior", "behavior_mean", "6",
    "How likely are you to engage in the following in the next 12 months? — Eat less meat", "0–100",
  "Donation to AMS", "donation_ams", "1",
    "Of the $10 bonus, how much would you like to donate to the American Meteorological Society (AMS)?", "$0–10",
  "Newsletter signup", "newsletter_signup", "1",
    "Subscription to the \"Talking Climate\" newsletter, offered on an earlier survey page (recorded yes/no).", "0 / 1"
) |>
  # zero-width break after each underscore so long variable names wrap
  mutate(Variable = str_replace_all(Variable, "_", "_\u200b")) |>
  tt(width = c(0.20, 0.18, 0.06, 0.46, 0.10)) |>
  format_tt(escape = TRUE) |>
  style_tt(align = "l", alignv = "t") |>
  style_tt(i = 0, bold = TRUE) |>
  style_tt(j = 2, monospace = TRUE) |>
  style_tt(fontsize = 0.85)
```
## About this preregistration {#sec-about}
**Why a second preregistration.** The project began as a single-team simulation study, preregistered as *"Predicting the effects of behavioral interventions on humans with LLMs"* (the original preregistration, **v1**). That plan asked how well one approach, an individual-level simulation built by members of the core team from demographically representative U.S. profiles with one particular model and prompt, recovers a novel megastudy. But a single team's result is only one point in a large space of ways to build a synthetic sample. We therefore decided to turn the project into a **multi-team benchmark** in which many independent teams predict the same novel experiment with any AI-based approach, and every approach is scored identically. This new preregistration plan supersedes the original **v1** preregistration.
**What it keeps from v1.** The human target study and the estimands (average treatment effects per intervention × outcome, subgroup interactions, control-condition response distributions, and demographic baselines), the three-section analysis structure (with the control-condition distribution analyses now grouped under [Section 3](#sec-section-3)), the least-to-most-strict ordering of the comparison metrics, and the preregistered split-half **human replication reference** are all carried over from v1. All are restated below (see [*Analysis plan*](#sec-analysis-plan)) to keep this new preregistration self-contained. The model functions are reused unchanged.
**What happens to v1's own simulations.** v1 came with two fully generated clone datasets (`google-gemini-2.5-flash-lite` and `openai-gpt-4o-mini`), publicly locked on Zenodo on May 13, 2026, the day before human data collection began ([doi:10.5281/zenodo.20167059](https://doi.org/10.5281/zenodo.20167059)). These datasets are **excluded from the benchmark**.
**What it changes and adds.** The changes fall into two groups. Group A gives the key design changes. Group B lists the changed and added evaluation metrics. Each change is summarized here, with a pointer to the section that specifies it in full.
Because this preregistration is written for teams who are blinded to the human outcome data, revising the analysis plan does not carry the usual risk of data-contingent researcher degrees of freedom.
**A. From one approach to a field.** These turn the study into a multi-team benchmark and set what it reports.
1. **Single team → multi-team benchmark.** The project now evaluates a *field* of independent submissions rather than one core-team approach. No member of the core team makes a submission, so every approach comes from an independent team. See [*Benchmark design*](#sec-benchmark-design).
2. **Method registration and disclosure.** Every team documents its pipeline on a standardized method-registration form (an extended GUIDE-LLM checklist) and deposits its predictions under a disclosure policy that keeps even proprietary entries verifiable. See [*Method registration and disclosure*](#sec-method-registration).
3. **Tiers of predictions.** The project now allows for submissions at different levels (Tier 1 individual-level synthetic data, Tier 2 cell-level statistics, Tier 3 effect-level estimates). See [*Three levels (tiers) of submissions*](#sec-tiers).
4. **Main results are about the field, not individual approaches.** The primary results will showcase distributions of predictive quality across the whole field of approaches. For comparison, we will add a split-half **human replication reference** (how well one half of the human sample predicts the other). See [*Benchmark design*](#sec-benchmark-design).
**B. Changes and additions to the evaluation metrics.** Items 5 to 7 revise metrics inherited from v1. The rest add new metrics, most of them following how recent silicon-sample studies evaluate synthetic samples.
5. **Two significance-based metrics dropped.** v1 scored its simulated sample partly by significance verdicts: inferential agreement (does the predicted effect reach the same significance verdict as the human effect?) and an equivalence test. Both need a standard error for each predicted effect, which v1 had because its effects were computed from an individual-level simulated dataset. In the benchmark, Tiers 2 and 3 submit no individual-level data that would allow to calculate standard errors. Both metrics are therefore dropped, and the remaining metrics (direction, correlation, absolute error, calibration) need only the point predictions. See [*Comparison functions*](#sec-comparison-functions) and [*Presentation of findings*](#sec-findings).
6. **Baseline calibration without correlations.** v1's Section 3a reports a Pearson correlation over each moderator's group means. The benchmark drops it, because a correlation over three to seven group means is unstable and ignores level and scale, and instead rests on the RMSE of the group means, the demographic parity gap, and the per-group display. See [*Section 3 — Baseline Calibration*](#sec-section-3).
7. **Stereotyping read from the group gaps.** v1 reads stereotyping from the demographic R² comparison alone. But a higher R² in a synthetic sample than in humans can mean two things: the group differences are exaggerated, or the synthetic individuals answer too much alike, which shrinks the residual variance and inflates R² even when every group mean is right. The regression's group coefficients — the predicted group gaps next to the human ones — are therefore the primary stereotyping measure. We will keep reporting the R² comparison. Under-dispersion is diagnosed separately by the variance ratio. See [*Section 3 — Baseline Calibration*](#sec-section-3).
8. **A noise-corrected correlation and RMSE.** The human effects an approach is scored against are estimated from a (half-split) sample which is not perfectly representing the population. The resulting sampling noise can drag down the correlations between human and synthetic sample effects. Because the sampling noise is unrelated to predictive skill, we try to account for it. Following @ashokkumarLargeLanguageModels2026a, we report a noise-corrected correlation beside the raw one (the raw value remains the main metric). The same correction yields an adjusted RMSE. When a submission's errors are smaller than the sampling noise of the reference estimates, the adjusted RMSE is reported as 0 with a flag, stating it is indistinguishable from perfect at this reference precision.^[If instead we would count negative RMSE's as `NA`s, we would punish the best submissions.] See [*Comparison functions*](#sec-comparison-functions).
9. **A within-outcome companion correlation.** The pooled Pearson r conflates two different kinds of prediction qualities: which *outcomes* are movable at all and which *messages* work. To differentiate the latter, we additionally report the correlation computed within outcomes (each outcome's mean effect subtracted on both human and synthetic side respectively). See [*Presentation of findings*](#sec-findings).
10. **Floor and chance-level references.** RMSE has no natural zero to read it against. Adding a naive "predict no effect for everything" approach as a floor reference makes such scores more interpretable. Each approach can then be interpreted by its distance to that floor, and to the human reference [@ashokkumarLargeLanguageModels2026a; @cumminsThreatAnalyticFlexibility2025b]. For the directional agreement metric, we add an additional reference level: an "every message works" strategy. Every intervention was designed to *increase* trust, so if most human effects come out positive, an "every message works" strategy can beat the "predict no effect" strategy while not being any more sophisticated. See [*Comparison functions*](#sec-comparison-functions) and [*Presentation of findings*](#sec-findings).
11. **Subgroup distributions.** Averaging outcome distributions over demographic groups can hide an approach that serves most groups well but consistently misses one. We report the gap between the worst- and best-served group in terms of distribution similarity [@parkLLMAgentsGrounded2026], with under-dispersion as the headline distribution diagnostic, since too-similar synthetic responses are the problem the literature flags most often. Groups under 30 respondents are skipped and named, with their sizes, wherever they are reported. See [*Section 3 — Baseline Calibration*](#sec-section-3).
12. **A fourth distribution metric, on a fixed grid.** Beside v1's variance ratio, OVL, and KS, the response-distribution analyses add the Wasserstein-1 distance (W1), a bandwidth-free companion to the KDE-based OVL. The OVL and W1 are evaluated over a grid fixed to each outcome's full scale range (0–100 for the sliders, $0–10 for the donation), identical for every submission, where v1's observed minimum-to-maximum range would score every submission on a slightly different grid. See [*Comparison functions*](#sec-comparison-functions) ([*Distribution comparison metrics*](#sec-distribution-metrics)).
13. **Human sample split robustness.** The human sample is divided in half at random to build the reference. That split is fixed before any data are seen, so it is not a researcher degree of freedom. But the particular split we drew is still arbitrary, and another random split would serve just as well. To show the results do not hinge on the one we happened to draw, we recompute them across many alternative splits and report how stable they are [@cumminsThreatAnalyticFlexibility2025b]. See [*Presentation of findings*](#sec-findings).
14. **One unit for all outcomes.** The outcome measures use different scales, with 0–100 attitude sliders, a $0–10 donation, and a 0–1 signup probability. To make effects on these scales comparable, we convert them to **percentage points of its outcome's scale range** before any cross-outcome scoring, following the practice of @ashokkumarLargeLanguageModels2026a. By contrast to v1, the binary newsletter outcome — already part of the ATE analysis through the logistic model's marginal effects, and excluded from the distribution metrics as a binary outcome in v1 — is newly added to the subgroup analysis on the same footing, via the linear probability model. See [*Presentation of findings*](#sec-findings) ([*Scoring principle*](#sec-scoring-principle)) and [*Section 2 — Subgroup Effects*](#sec-section-2).
15. **A pooled calibration regression.** v1 runs the calibration regression per outcome, on 16 points each. The benchmark instead pools all condition × outcome pairs into one regression (16 × 13 = 208 points, in percentage points of scale range). See [*Comparison functions*](#sec-comparison-functions) ([*Calibration regression*](#sec-calibration-regression)).
16. **Calibration reported descriptively.** v1 tested calibration with two F-tests (the joint α = 0, β = 1 and the slope-only β = 1) and reported the regression's R². The benchmark drops the tests and the R², and reports α and β with 95% cluster-bootstrap CIs, read descriptively. At this reference precision (roughly 18,000 humans behind 208 points) every realistic approach rejects exact calibration, so the tests would not separate approaches, and their p-values would be overconfident because the pooled points are not independent. The R² goes because it equals the squared pooled Pearson r already on the leaderboard. See [*Comparison functions*](#sec-comparison-functions) ([*Calibration regression*](#sec-calibration-regression)).
17. **A noise-corrected calibration slope for Tier 1.** Sampling noise in the *predicted* effects drags the calibration slope toward zero (noise in the human reference doesn't, it only widens the residuals). Because Tier-1 effects are refit by us, their standard errors are known, and we report a corrected slope beside the raw one: raw β divided by the reliability of the predicted effects. See [*Comparison functions*](#sec-comparison-functions) ([*Calibration regression*](#sec-calibration-regression)).
18. **Scoring without covariate adjustment.** The human study's main models adjust for age, gender, and race to gain power, and v1 inherited that specification. The benchmark's scoring models are all fit without covariates, on both the human and the submission side, because Tier 2 and 3 predictions are bare cell means and effect estimates (unadjusted by construction). See [*The human target sample*](#sec-human-sample) and [*Estimation functions*](#sec-estimation-functions).
19. **A wisdom-of-crowds ensemble row.** We compute the field's average prediction — within each intervention × outcome pair, the mean predicted ATE across all entries — as a non-competing reference row. It tests whether averaging across prediction approaches may beat the best single prediction approach. For teams with several entries, a separate table additionally compares each team's within-team average against its primary entry. See [*Wisdom of crowds*](#sec-wisdom-of-crowds).
## The human target sample {#sec-human-sample}
Synthetic sample predictions are scored against the human data from the megastudy. Participants are recruited from a non-probability opt-in panel, quota-matched (age, gender and race) to the population of U.S. residents, all aged 18 or older, who pass a series of attention and bot-detection checks before treatment assignment.
The benchmark targets **N ≈ 18,000 complete responses**, with 1,000 per intervention across the 16 text-based interventions plus 2,000 in the shared control condition. Recruitment uses **census-based cross quotas** on gender × age and gender × race/ethnicity to approximate the U.S. adult population. The targets below match the proportions of the parent megastudy, with counts rescaled to a total N ≈ 18,000. Participants selecting "Other" as their gender are not quota-constrained.
The targets below are drawn from the 2024 U.S. Census Bureau Population Estimates Program. *Total* is the share within each category. *Male* and *Female* give the within-category gender split. The table describes the key demographics of the human sample. Participating teams are not required to use this information for their own synthetic sample.
```{r}
#| label: tbl-quotas
#| tbl-cap: "Sampling quota targets (N ≈ 18,000), from the 2024 U.S. Census Bureau Population Estimates Program. Proportions match the parent megastudy, with counts rescaled to N ≈ 18,000, while the target of the megastudy is N ≈ 22,000."
# Same layout as the interventions table: category headers inserted as bold
# full-width rows above their levels (tinytable, for a consistent look).
quotas <- read_csv(here("data/quotas_18000.csv"), show_col_types = FALSE)

quota_table_data <- quotas |>
  group_by(Variable) |>
  group_modify(~ bind_rows(
    tibble(Category = as.character(.y$Variable), Total = "", Male = "", Female = ""),
    .x
  )) |>
  ungroup() |>
  select(Category, Total, Male, Female) |>
  rename(` ` = Category)

header_rows_q <- which(quota_table_data$Total == "")

quota_table_data |>
  tt(width = c(0.40, 0.20, 0.20, 0.20)) |>
  format_tt(escape = TRUE) |>
  style_tt(align = "l", alignv = "t") |>
  style_tt(i = 0, bold = TRUE) |>
  style_tt(i = header_rows_q, bold = TRUE) |>
  style_tt(fontsize = 0.85)
```
Full sampling and exclusion detail is in the [human study preregistration](https://doi.org/10.5281/zenodo.20160212). The human reference estimates follow that preregistration's analysis plan, with one deviation: all scoring models, on both the human and the submission side, are fit **without covariate adjustment** (the `covariates` argument of the model functions is never used). The human study's main models adjust for age, gender, and race to gain power. Tier 2 and Tier 3 submissions are bare cell means and effect estimates, which are unadjusted by construction, so scoring them against an adjusted human reference would compare two different estimands.
**Differential attrition and weighting.** The human study preregisters two tests for differential attrition, one for whether completion rates differ between conditions and one for whether the composition of dropouts does. If these tests show heterogeneous differential attrition, the human reference models will apply inverse-probability weights, estimated as specified in the [human study preregistration](https://doi.org/10.5281/zenodo.20160212). If weights are applied, they apply to the effect estimates — the ATEs and the condition × moderator interaction estimates, in both human halves — and submissions are scored against the weighted estimates. All [Section 3](#sec-section-3) quantities stay unweighted. The demographic group means, the demographic parity gap built from them, the response distributions, and the predictability regressions describe the observed human respondents, and they are compared against the same plain, unweighted quantities computed from the synthetic respondents.
## Benchmark design {#sec-benchmark-design}
The primary goal of this project is to assess how well the research field of synthetic samples can predict the results of the behavioral experiment. It reports the distribution of predictions across submissions on each metric, its center and spread. The secondary goal is to rank individual approaches on the evaluation metrics.
Participation is by invitation. The reason not to have an open call is to have a selection of experts with a track record on synthetic sampling and that can be taken to represent the field. That said, the invited experts are of course not a random sample for two reasons. First, our invitation list does not capture the entire population of relevant experts. Second, contacted experts self-select into participating, with some not opting to participate for various reasons.
Each team builds an AI-based prediction pipeline from the shipped materials, including intervention texts, the full survey instrument, the codebook, and the registration template. Teams can use any models, personas, prompts, fine-tuning, retrieval, or prior data and literature they want. Before the prediction lock deadline, each team registers its approach by depositing its synthetic sample/predictions and materials on Zenodo, hashed and time-stamped. The deposit logistics (Zenodo record structure, the `metadata.json` file, file naming, the self-check validator, and the public/escrowed split) are specified in the [call for participation](index.html) and the [benchmark submission template repository](https://github.com/janpfander/silicon-sample-submission).
After the prediction lock deadline, every submission runs through the preregistered analysis pipeline unchanged and is reported on a public leaderboard alongside the human replication reference, and in a joint manuscript with all participating teams as co-authors. There are three ground rules for an entry to be valid: **No data access.** By design, no participating team has access to the human data. **Pipelines are AI-based and automated.** Predictions may be made based on previously published human data, but no new human data specific to this project may be collected. **Everything is registered** (see the disclosure policy below). The full procedure, ground rules, timeline, and incentives are in the [call for participation](index.html).
Every submission must cover all 16 interventions and all 13 outcomes. Predicting a selected, potentially easier-to-predict subset of effects would make for an unfair comparison to submissions attempting to predict all effects, so partial submissions are not accepted.
### Blinding and data access {#sec-blinding}
The collected human data (all ~18,000 responses, collection complete at the time of writing) have been accessed only by the research lead, Jan Pfänder, for data-quality monitoring and for the preliminary interim results presented at the talks disclosed below. No member of the core team enters the benchmark.
For full disclosure, Jan Pfänder presented preliminary results from the v1 simulation (the superseded single-team preregistration, see [*About this preregistration*](#sec-about)) in a five-minute talk at a closed academic workshop at the Max Planck Institute for Human Development in Berlin (May 2026). This is the only presentation that has targeted an audience that includes potential benchmark participants, so we state precisely what it showed. For the two public v1 clone datasets, the slides showed scatter plots of preliminary human ATEs (human sample at the time N ≈ 3,500 of the planned 22,000) against the clone ATEs — one unlabeled point per intervention × outcome, with fitted regression lines and pooled correlation coefficients — and control-condition response-density overlays of humans and clones for a few illustrative outcomes. The spoken conclusion was that prediction did not look good at that stage. Two other talks were explicitly about the human megastudy results. Jan Pfänder presented preliminary results from the human megastudy at an invited talk at the Max Planck Institute for Human Development in Berlin (May 2026, N at the time ≈ 3000 of 22000), and at a small conference at the University of Hohenheim (June 2026, N at the time ≈ 13000 of 22000). These talks did not target an audience of researchers in the field of synthetic sampling. We will require a signed declaration of whether they had attended any of these talks from all participating teams. If there are teams who had, we will run robustness checks that exclude their submissions. In addition, since we ask for extensive disclosure of materials, a "cheating" prompt (e.g., "make sure intervention XX does best") would surface in the reporting framework that teams are required to fill out.
### Three levels (tiers) of submissions {#sec-tiers}
Teams submit their predictions at one of **three tiers**, defined by the granularity of the prediction. Each team chooses the highest tier its approach supports. Lower tiers are simply eligible for fewer analyses.
- **Tier 1 · Individual-level synthetic data.** Eligible for everything, meaning ATE recovery, calibration regression, response distributions, subgroup heterogeneity, demographic baselines, and stereotyping diagnostics. *Grain: 1 row = 1 synthetic respondent.*
- **Tier 2 · Group-level treatment effect predictions.** Eligible for ATEs, calibration, subgroup heterogeneity, and demographic baselines. Not eligible for the distribution-shape metrics (variance ratio, OVL, KS, W1) or the predictability regressions. *Grain: 1 row = 1 cell (condition × [moderator level ×] outcome).*
- **Tier 3 · Average treatment effect predictions.** Eligible for ATE recovery and the calibration regression. *Grain: 1 row = 1 intervention × outcome estimate.*
| Preregistered analysis | Tier 1 | Tier 2 | Tier 3 |
|---|:-:|:-:|:-:|
| ATE recovery (Section 1) | ✓ | ✓ | ✓ |
| Calibration regression $\alpha$ / $\beta$ (Section 1) | ✓ | ✓ | ✓ |
| Subgroup heterogeneity, condition × moderator (Section 2) | ✓ | ✓ | — |
| Response distributions, variance ratio, OVL, KS, W1 (Section 3) | ✓ | — | — |
| Within-subgroup distributions (Section 3) | ✓ | — | — |
| Demographic baseline calibration (Section 3) | ✓ | ✓ | — |
| Demographic predictability / stereotyping (Section 3) | ✓ | — | — |
#### Tier 1 — individual-level dataset {#sec-tier-1}
One row per synthetic respondent, with the columns listed below (an example file is provided in the submission template repository).
| Column(s) | Type | Specification |
|---|---|------|
| `profile_id` | string | A unique respondent identifier you assign (unique within the submission). |
| `condition` | factor | `control` (lowercase) or one of the 16 intervention titles, exactly as in `survey/condition_codenames.csv`. |
| `gender`, `age_band`, `race`, `education`, `income`, `party` | factor | The six moderators, levels per codebook (from your own profiles). |
| `trust_multidimensional` + 12 trust items | numeric | Primary composite 0–100. The 12 underlying items per codebook scale. |
| `trust_post`, `distrust_post`, `funding_perceptions`, `policy_role_mean`, `inst_trust_mean` | numeric | Secondary outcomes, original scales per codebook. |
| `belief_post`, `concern_mean`, `policy_general`, `policy_specific_mean`, `behavior_mean` | numeric | Tertiary outcomes, original scales per codebook. |
| `donation_ams` | numeric | Donation to AMS in $, per codebook. |
| `newsletter_signup` | 0 / 1 | Binary behavioral outcome. |
Because a Tier 1 submission has the same shape as the human participant data, the same analysis code applies.
**Precision requirement.** The precision of an approach's estimated effects depends on the size of the synthetic sample. The fewer synthetic respondents, the noisier each estimated effect. Sampling noise can confound the assessment of a synthetic sampling approach: A very small sample would score poorly for a reason that has nothing to do with the method. A Tier 1 submission must therefore contain at least as many synthetic respondents as the human half it is scored against, meaning **500 per intervention and 1,000 in the control condition**. At that size the submission's effects carry about the same sampling noise as the human reference. We encourage teams to go well beyond this minimum. A larger synthetic sample gives more precise effect estimates that reflect the method rather than the luck of a particular draw, and synthetic respondents are relatively cheap to generate.
#### Tier 2 — cell-level file(s) {#sec-tier-2}
Two long-format files. `*_cells_main.csv` has one row per condition × outcome, and `*_cells_moderator.csv` one row per condition × moderator × moderator-level × outcome. Overall ATEs are derived from the main file (treatment minus control cell mean) and subgroup estimates from the moderator file, so no separate effect-level file is needed.
| Column | Type | Specification |
|---|---|------|
| `condition` | factor | Per `survey/condition_codenames.csv` (lowercase `control`). |
| `moderator`, `moderator_level` | factor | Moderator file only. Levels per codebook. |
| `outcome` | string | Outcome variable name per codebook. |
| `mean` | numeric | Predicted cell mean on the original scale (proportion for `newsletter_signup`). Both files must be complete, with no `NA` cells. To predict *no moderation* for a demographic group, repeat the condition mean from the main file in that group's cells. |
#### Tier 3 — effect-level file {#sec-tier-3}
One row per intervention × outcome (16 × 13 = 208 rows). Estimates are ATEs versus control on the original outcome scale. The binary outcome is on the probability scale.
| Column | Type | Specification |
|---|---|------|
| `condition` | factor | Intervention title per `survey/condition_codenames.csv`. |
| `outcome` | string | Outcome variable name per codebook. |
| `ate` | numeric | Predicted ATE, original units. |
### Scoring principle {#sec-scoring-principle}
Each approach will be scored on a set of evaluation metrics (see below). For the main analyses, the treatment effect estimates will be pooled across all outcomes and interventions. Some of the 13 outcomes are on different scales. The 11 attitudinal outcomes use sliders from 0 to 100, the two behavioral outcomes differ. The donation outcome ranges from \$0 to \$10, and the newsletter signup is binary. To pool estimates across these different scales, every estimate and standard error is converted to percentage points (pp) of its outcome's scale range [following @ashokkumarLargeLanguageModels2026a].^[As @ashokkumarLargeLanguageModels2026a note, the common alternative, dividing each effect by a standard deviation to get a standardized effect size (e.g., Cohen's d), is problematic: synthetic respondents are known to answer too much alike, which makes the synthetic SD too small, and dividing by a too-small SD would exaggerate the predicted effects.] The conversion into percentage points is a modeling choice which equates 3 points on a 0–100 slider with $0.30 on the donation and 3 pp of signup probability.
We deliberately do not collapse the metrics into one composite "champion" score. An approach can recover the direction of effects well while mis-scaling them, or do well on the primary outcome while doing badly on other outcomes. This inconsistency across outcome metrics has been observed in other studies [@cumminsThreatAnalyticFlexibility2025b].
### Entries per team {#sec-entries}
Each team may submit up to three entries per tier (up to nine in total). This strikes a balance between providing a team with the opportunity to try out different approaches, and ensuring that no single team dominates by submitting a large number of approaches. Where a team has good reasons to systematically vary some aspect of its approach, we may grant additional entries on request, but only three per tier enter the main analyses.^[Additional entries, in such a case, would at most be discussed in supplemental materials.] Each team designates only one of its entries, across all tiers, as its **primary entry** before the prediction lock. The primary entry is supposed to capture each team's single best effort. As a robustness check to ensure that any of our findings on "the field" are not overly influenced by one team, the main results will be recomputed on primary entries only (see [*Primaries-only robustness*](#sec-primaries-only)).
In all figures and summary tables, the teams' submissions will appear under neutral labels (e.g., `submission_1` for a single-entry team, and `submission_2_a`, `submission_2_b`, … for a multi-entry team, with `_a` the team's primary entry). The neutral labels reflect the idea of a field benchmark, rather than a tournament. A table (likely in the supplemental materials, @tbl-submission-teams) will map each label to its team.
### Method registration and disclosure {#sec-method-registration}
Before the prediction lock, every team documents its pipeline on a structured **method-registration form** and deposits it alongside the predictions. The form builds on the GUIDE-LLM reporting checklist [@feuerriegelReportingChecklistLarge2026]. The form and the **disclosure policy** (which lets proprietary teams seal items under escrow while keeping the lock publicly verifiable) are published in the [call for participation](index.html#registration-form). We provide a template in the [benchmark submission template repository](https://github.com/janpfander/silicon-sample-submission).
## Analysis plan {#sec-analysis-plan}
### The human replication reference {#sec-overview}
Each submission is scored against the same human sample. The human sample is split into two halves by a preregistered random seed (seed 42, set in the setup chunk above). **Human 1** is the reference half every submission is scored against. **Human 2** predicts Human 1 like any submission would, and its scores define the **human replication reference**, which shows how well a fresh human sample of this size reproduces the reference half. This human reference is evaluated in the same way as a Tier-1 synthetic submission. Human 2 is not necessarily a ceiling reference, as it carries sampling noise. A synthetic submission built on a much larger sample could score above it.
We add two additional baseline references: "no effect" and "all positive". These provide references for the metrics without a natural null (see [*Presentation of findings*](#sec-findings)). Because the split seed for the human sample is an arbitrary choice, we will provide robustness checks across many alternative splits, so that results do not hinge on the seed we happened to select ([*Robustness of the scoring pipeline*](#sec-pipeline-robustness), below).
Which of the analyses below applies to a given submission follows from its tier (see [*Three levels (tiers) of submissions*](#sec-tiers)). Tier 1 is eligible for all of them, Tiers 2–3 for the estimate-based subset.
### Estimation functions {#sec-estimation-functions}
This set of functions produces the average treatment effects per intervention for [Section 1](#sec-section-1) and the condition × moderator interactions for [Section 2](#sec-section-2). These functions are taken from the [human study preregistration](https://doi.org/10.5281/zenodo.20160212), where their full statistical rationale is given, with one small addition: `run_moderator_model()` here also returns the moderator's reference level (`moderator_baseline`) beside the condition's, since every interaction coefficient is a contrast against it. We reproduce the functions here so this document stands alone. As stated under [*The human target sample*](#sec-human-sample), no scoring model uses the functions' `covariates` argument.
`run_main_treatment_model()` estimates each intervention's ATE against the shared control by OLS with HC2 heteroskedasticity-robust standard errors and BH-adjusted p-values.
```{r, results='asis'}
#| label: fn-run-main-treatment-model
print_a_function_from_file("run_main_treatment_model")
```
`run_main_treatment_model_binary()` is the counterpart for the binary newsletter-signup outcome. It fits a logistic regression and returns marginal effects on the probability scale.
```{r, results='asis'}
#| label: fn-run-main-treatment-model-binary
print_a_function_from_file("run_main_treatment_model_binary")
```
`run_moderator_model()` estimates the condition × moderator interactions used for the subgroup analysis ([Section 2](#sec-section-2)). For the binary newsletter-signup outcome the benchmark's subgroup scoring runs this same OLS function as a linear probability model: in the condition × moderator specification, the OLS interaction coefficient equals the difference-in-differences of the cell signup proportions, in probability units, which convert to percentage points like every other outcome.^[A logistic model gives the same number: both saturated models fit the cell proportions exactly, so converting the logit back to the probability scale (as `run_main_treatment_model_binary()` does via marginal effects for the ATEs) and taking the second difference reproduces the identical difference-in-differences.] The advantage of the linear probability model is that it stays defined when a small demographic cell contains no signups at all, a case in which the logit coefficients diverge.
```{r, results='asis'}
#| label: fn-run-moderator-model
print_a_function_from_file("run_moderator_model")
```
### Comparison functions {#sec-comparison-functions}
The comparison metrics are implemented by a small set of helper functions, applied symmetrically to the human reference and to each submission.
#### Comparison metrics {#sec-comparison-metrics}
The estimate-based metrics compare the point estimates of a submission with those of the human reference, for ATEs ([Section 1](#sec-section-1)) and moderator interaction estimates ([Section 2](#sec-section-2)). Each metric is computed once per submission, across all interventions and all outcomes together (all estimates in the common unit, see [*Scoring principle*](#sec-scoring-principle), above). The by-outcome and by-intervention breakdowns apply the same functions to the corresponding subsets. The metrics are reported in increasing order of strictness and implemented in `pooled_metrics()` (shown under [*Scoring functions*](#sec-scoring-functions), below).
- **Directional agreement (%)**. The share of estimates with the same sign as the human estimate. Does the approach at least get the direction of each effect right? A predicted exact zero makes no directional claim and therefore needs a scoring rule. Counted as wrong, a zero would be punished like a prediction of the opposite direction. Counted as correct, it would earn points for claiming nothing. Dropped from the denominator, zeros would be free abstentions, and a team could write zeros for the pairs it is unsure about and be scored only on its confident calls. Exact zeros therefore score **half credit**, the expected score of a blind guess. A team then neither gains nor loses by writing zeros instead of guessing, and every pair stays in every submission's denominator. The chance level to read this metric against is *not* 50%: every intervention was designed to increase trust, so if most human effects come out positive, a mindless "every message works" strategy beats 50% without any skill. The empirical chance level is the share of positive human ATEs, reported as the all-positive baseline row in the leaderboard.
- **Spearman $\rho$**. The rank correlation of the point estimates. Does the approach rank the effects — all intervention × outcome pairs in one ranking — in the same order as humans? It is insensitive to scale or offset, so an approach that inflates all effects equally still scores $\rho$ = 1.
- **Pearson r**. The linear correlation of the point estimates. It captures whether predicted and human effects move together in proportion, but not whether their absolute size matches (see [*Calibration regression*](#sec-calibration-regression), below).
- **Pearson r within outcomes**. The pooled Pearson r mixes two different kinds of prediction quality: predicting which *outcomes* move due to interventions and knowing which *messages* work. Predicting which kinds of outcomes (e.g., attitudinal vs. behavioral) are more prone to change after behavioral interventions might reflect generic knowledge of past research, while predicting which new interventions will work might be a more difficult, out-of-the-box capacity. We therefore also report the correlation computed within outcomes. To do so, we mean-center within outcomes on both sides: from each intervention's effect on an outcome, we subtract that outcome's mean effect across all interventions, separately for the human and the predicted effects.^[This is the same as adding outcome fixed effects to a regression of human on predicted effects.] The resulting estimate captures message-level skill, and the gap to the pooled r says how much of the pooled score came from outcome-level knowledge.
- **RMSE**. The root mean squared error, the average size of the prediction errors, expressed like every pooled metric in percentage points of scale range (see [*Scoring principle*](#sec-scoring-principle), above). RMSE has no natural zero, so it is read against the two reference rows in the leaderboard: the no-effect floor and the human replication reference. Beating the floor is a low bar, since the floor predicts zero for every intervention, and a submission can pass it by predicting a plausible uniform average effect without distinguishing the interventions.
#### Adjusted correlation and RMSE (noise-corrected) {#sec-adjusted-metrics}
The effects in the human sample are noisy. That noise mechanically drags the correlation between effects of the human and synthetic sample down, because it inflates the observed spread of the reference effects. The raw Pearson r divides by that inflated spread and, as a result, is biased toward zero. The same noise inflates the RMSE.
Wherever Pearson r appears in the cross-team analysis we therefore report, beside the raw value, a noise-corrected correlation **r~adj~** and a noise-corrected RMSE (`adjusted_metrics()`). The correction works by subtraction. If we assume the sampling noise to be independent, the true spread of the reference effects is their observed spread minus the average known sampling variance. The adjusted correlation divides the covariance by that corrected spread (Spearman disattenuation with known error variances). This method is similar to the meta-analytic r~adj~ of @ashokkumarLargeLanguageModels2026a, but uses fewer assumptions. As @ashokkumarLargeLanguageModels2026a, we will report r and r~adj~ side by side in the manuscript. This allows us to directly compare our results to their larger megastudy archive, the closest analogue to this benchmark^[We take Ashokkumar et al.'s megastudy figures, not their headline r = .85, as the reference because the two numbers measure different tasks. The .85 is a correlation over 469 effects pooled from 70 unrelated survey experiments, spanning many topics, treatments, and outcomes. Their megastudy figures instead measure how well the model distinguishes the several interventions of a single megastudy against that study's shared control, which is exactly this benchmark's setting (16 interventions, one control). Ashokkumar et al. report the megastudies as a separate secondary archive (15 megastudies, 606 effects) and note that these correlations are lower than the primary archive's.], survey experiments reach r = .43 (r~adj~ = .52) and text-based treatments r = .45 (r~adj~ = .54).
The adjusted RMSE applies the same logic to the RMSE. It subtracts the average reference sampling variance from the average squared prediction error and takes the square root. When a submission's errors are smaller than the reference sampling variance, the subtraction goes negative. The adjusted RMSE is then reported as 0 with a flag, meaning the submission's errors are at or below the sampling noise of the human reference estimates — indistinguishable from perfect at this reference precision. The same rule applies inside every bootstrap replicate (an NA would drop exactly the best replicates from the interval).
```{r, results='asis'}
#| label: fn-adjusted-metrics
print_a_function_from_file("adjusted_metrics")
```
#### Distribution comparison metrics {#sec-distribution-metrics}
`compare_distributions()` compares response distributions for a single condition and outcome using four metrics:
- **Variance ratio** (submission variance / human variance). It captures only relative spread. A ratio of 1 means equal spread and says nothing about shape. A ratio below 1 means the synthetic responses vary less than the human ones, the most widely reported problem with synthetic samples.
- **OVL (overlapping coefficient)**. The share of area the two kernel density estimates have in common (1 = identical distributions, 0 = no overlap). It summarizes overall shape similarity.
- **KS D-statistic**. The largest gap between the two empirical cumulative distributions (0 = indistinguishable everywhere). It is sensitive to local departures that OVL might average away.
- **Wasserstein-1 distance (W1)**, enabled with `include_w1 = TRUE` (new in this preregistration). The area between the two cumulative distributions, in outcome scale points (0 = identical). It is the bandwidth-free companion to OVL: kernel density estimates depend on bandwidths, which change with sample size and leak density past the 0/100 scale bounds, while W1 has no tuning parameter.
In the benchmark, the OVL and W1 evaluation grid is fixed to each outcome's full scale range (0–100 for the sliders, $0–10 for the donation), so every submission is scored on the identical grid. With the function's default empirical grid — the observed minimum-to-maximum of the two samples — the resulting areas would not be comparable across submissions.
```{r, results='asis'}
#| label: fn-compare-distributions
print_a_function_from_file("compare_distributions")
```
```{r, results='asis'}
#| label: fn-compute-ovl
print_a_function_from_file("compute_ovl")
```
```{r, results='asis'}
#| label: fn-compute-w1
print_a_function_from_file("compute_w1")
```
#### Calibration regression {#sec-calibration-regression}
Correlation tells us only whether the human and predicted effects covary. It does not capture baseline differences or scaling. An approach could inflate every effect by a factor of two and still score Pearson r = 1. The calibration regression captures this.
`run_calibration_pooled()` regresses human ATEs on predicted ATEs, $\mathrm{ATE}_{human} = \alpha + \beta \times \mathrm{ATE}_{predicted}$, across all condition × outcome pairs pooled over the 13 outcomes (16 × 13 = 208 points, every estimate in pp of scale range). The two coefficients separate two kinds of prediction error: $\beta$ catches proportional error, which grows with the size of the effect, and $\alpha$ catches additive error, the same absolute amount for every effect. The slope $\beta$ captures whether the synthetic samples systematically exaggerate effects. If $\beta = 1$, there is no exaggeration. If $\beta$ is below one, the predictions are exaggerated. For example, $\beta = 0.5$ means the predictions exaggerate every difference by a factor of two. The intercept $\alpha$ is the human effect the fitted line expects when the approach predicts no effect at all. If $\alpha = 0$, offset calibration is perfect. A positive $\alpha$ means the human effects sit above the predicted ones by a constant amount, across all interventions and outcomes. That happens when something lifts every human effect equally, regardless of which message it is. An approach whose synthetic respondents miss this across-the-board lift underpredicts every effect by the same amount. We report $\alpha$ and $\beta$ with 95% intervals and read them descriptively. We do not test the point hypotheses $\alpha = 0$ and $\beta = 1$. The reported intervals come from the intervention cluster bootstrap, the same resampling (identical seed and draws) that produces every other uncertainty interval in the cross-team analysis (see [*Uncertainty interval functions*](#sec-uncertainty-intervals)).
A slope below 1 has two possible readings. The first is genuine exaggeration: the approach systematically predicts more extreme effects than humans show. The second is sampling noise in the predictions themselves. Noise in the *human* effects never biases the slope (it only widens the residuals), but noise in the *predicted* effects drags the slope toward zero by the reliability of the predictions, $\lambda = 1 - \overline{se_{pred}^2} / \mathrm{var}(\mathrm{ATE}_{predicted})$. A Tier-1 entry that is perfectly calibrated but uses a small synthetic sample can therefore print a raw $\beta$ well below 1, only because of its sample size. For Tier-1 entries^[Tiers 2–3 submit point predictions with no standard errors, so no correction exists there, and a $\beta$ below 1 reads as exaggeration, prediction noise, or both.] - whose effects we fit ourselves so we know their standard errors - we report a corrected slope beside the raw one: $\beta_{adj} = \beta / \hat{\lambda}$, the slope of the entry's latent (if they would have used an infinitely large sample) predictions. The raw $\beta$ remains the main outcome, and the value comparable to @ashokkumarLargeLanguageModels2026a: small synthetic samples are simulation choices, and if they result in poor calibration, that is part of evaluating the prediction success. The $\beta_{adj}$ is of secondary interest, to compare how much each approach would exaggerate in a world with equal (infinite) sample sizes across approaches.
```{r, results='asis'}
#| label: fn-calibration
print_a_function_from_file("run_calibration_pooled")
```
#### Demographic baseline and predictability metrics {#sec-demographic-metrics}
`compare_demographic_baselines()` computes, for each moderator, the RMSE between human and synthetic sample cell means in the control condition. `compare_demographic_predictability()` fits separate OLS regressions of the outcome on each moderator plus condition fixed effects, returning $R^2$ and dummy-coded coefficients for humans and for the submission. `demographic_parity_gap()` quantifies, for each moderator, the gap between the worst- and best-served demographic group in the control condition. For example, if an approach's control-condition baseline is off by 6 pp for Republicans but only 1 pp for Democrats, the parity gap for partisan identity is 5 pp, with Republicans the worst-served group. Groups under 30 respondents on either side are skipped, and the skipped groups are named, with their sizes, wherever the parity gap is reported (see [*Section 3 — Baseline Calibration*](#sec-section-3)).
```{r, results='asis'}
#| label: fn-demographic-baselines
print_a_function_from_file("compare_demographic_baselines")
```
```{r, results='asis'}
#| label: fn-demographic-predictability
print_a_function_from_file("compare_demographic_predictability")
```
```{r, results='asis'}
#| label: fn-demographic-parity-gap
print_a_function_from_file("demographic_parity_gap")
```
#### Scoring functions {#sec-scoring-functions}
The comparison metrics above are defined for a single approach. The scoring functions below apply them at the benchmark's scale: they compute each submission's pooled scores and summarise the resulting scores across all approaches (see [*Presentation of findings*](#sec-findings), below).
`pooled_metrics()` computes the ATE-recovery metrics on intervention × outcome pairs pooled across all outcomes: directional agreement, Spearman $\rho$, Pearson r, and the noise-corrected companion r~adj~ (via `adjusted_metrics()`, see [*Adjusted correlation and RMSE (noise-corrected)*](#sec-adjusted-metrics), above). The pairs it receives are already in pp of scale range, converted once at pair-building time, so `include_rmse = TRUE` adds RMSE and RMSE~adj~ in pp, used for the pooled leaderboard as well as the per-outcome breakdown. It expects pre-joined pairs with the reference (Human 1) columns `estimate_h`, `se_h` and the submission column `estimate_l`.
```{r, results='asis'}
#| label: fn-pooled-metrics
print_a_function_from_file("pooled_metrics")
```
`signed_metrics()` is the subgroup counterpart: directional agreement, Spearman $\rho$, and Pearson r (plus r~adj~ where the human interaction standard errors are available) on the interaction pairs, matching [*Section 2 — Subgroup Effects*](#sec-section-2), below.
```{r, results='asis'}
#| label: fn-signed-metrics
print_a_function_from_file("signed_metrics")
```
`metrics_by_group()` scores within each level of a grouping variable. With `group = "outcome"` it returns one set of metrics per outcome (scored across the interventions), and with `group = "condition"` one per intervention (scored across the outcomes). Per intervention the score runs across `outcomes_continuous` only: the pp conversion removes the *unit* mix, but a per-intervention correlation across all 13 outcomes would still mix attitude and behavioral constructs.
```{r, results='asis'}
#| label: fn-metrics-by-group
print_a_function_from_file("metrics_by_group")
```
`summarise_field()` reduces the per-approach scores to the field-level summary printed beside the headline figure, giving the mean, median, SD, min, and max of each metric across approaches (excluding the reference row).
```{r, results='asis'}
#| label: fn-summarise-field
print_a_function_from_file("summarise_field")
```
### Uncertainty interval functions {#sec-uncertainty-intervals}
Each cross-team score is a single pooled number. But if one approach scores Pearson *r* = 0.60 and another 0.55, is the first genuinely better, or is the gap an artifact of the particular interventions that happened to be tested? To address this question, we use bootstrap intervals.
The pooled metric is computed once on the full data to give the point estimate. We then form a *cluster bootstrap over interventions* (`cluster_boot()` in `R/functions/statistics.R`, preregistered seed 2026). Each replicate draws 16 interventions with replacement (so some are drawn twice and some are dropped), and each drawn intervention brings along its rows for all outcomes, because rows that share an intervention are not independent. The pooled metric is recomputed on each replicate, and the 2.5th to 97.5th percentiles of those recomputed scores give the 95% interval. The 13 outcomes themselves are never resampled: they are a fixed design feature of the megastudy, so the interval reflects only uncertainty over which interventions were tested. How scores vary across outcomes is shown descriptively in the per-outcome breakdown ([*Where the field predicts well*](#sec-field-by-group)), whose per-outcome values rest on just 16 pairs each and therefore carry no intervals of their own.
**Assumptions.** The interval treats the 16 interventions as a sample from the broader space of possible interventions. It asks: would this approach's score, and its rank, survive on a different set of interventions of the same kind? A wide bar signals that a score is flimsy and may reflect test-set luck rather than generalizable prediction skill.
Why resample interventions and not outcomes? Because the two dimensions have different status in the design. The messages were contributed by independent intervention-author teams — a real sampling process from the space of what researchers would propose — and the benchmark's forward-looking question (could synthetic samples pre-screen the *next* batch of candidate messages?) is a question about new messages measured on the same instrument. The 13 outcomes, in contrast, are the megastudy's fixed outcome battery: they define the research question rather than sample from a population, and how scores vary across them is a finding shown descriptively. There is also a mechanical reason: intervention arms contain disjoint respondents (each person sits in one condition), so they form approximately independent resampling units, while every respondent answers every outcome — outcome slices are built from identical people and could not serve as bootstrap clusters in an equally straightforward way.
Each interval describes the uncertainty of one approach's own score, in the same way that each arm of a multi-arm experiment is reported with a confidence interval against the shared control group. As in that case, the difference between two approaches is not tested by checking whether their intervals overlap. All scores are computed against the same human reference. We use identical bootstrap draws for every team, so that two teams' intervals then differ only because their predictions differ, never because of resampling luck. The scores of two approaches are therefore correlated, and their difference can be reliable even where their intervals overlap. We therefore present the ranking as descriptive and preregister no test of whether one approach outperforms another. In another prediction mass collaboration, the 160 submissions performed similarly, and prediction error depended far more on the case being predicted than on the technique used [@salganikMeasuringPredictabilityLife2020]. We expect small margins between top performers in our project, too. Two caveats apply to all bootstrap intervals. First, the intervals rest on only 16 clusters. The bootstrap can only re-combine the 16 intervention effects it has observed, and with so few units the spread of those re-combinations understates the true sampling variation. Second, every ATE is measured against the same control group. Chance noise in that one control mean moves all 16 ATEs up or down together, and the resampling never varies it: each replicate redraws which interventions enter but reuses the identical control mean, so this shared part of the sampling noise is missing from the intervals. Both caveats point in the same direction, and the intervals are read as approximations, likely somewhat too narrow.
**Relation to the per-effect standard errors.** The bootstrap interval is a different layer of uncertainty from the sampling error of the individual human effects. A per-effect standard error is *within-intervention*: it says how precisely a single human effect is estimated, and it enters the scoring only through the noise-corrected r~adj~ and RMSE~adj~. The bootstrap interval is *across-intervention*: it says how much the pooled score depends on which interventions were tested, holding each estimate fixed at its point value.
`cluster_boot()` attaches the uncertainty interval described above. It resamples the levels of a clustering variable (here, the interventions) with replacement, recomputes the supplied metric function on each replicate, and returns the point estimate together with percentile confidence bounds in long form (one row per metric, with `value`, `lo`, `hi`). It is generic. The metric function is passed in, so the same bootstrap serves every panel.
```{r, results='asis'}
#| label: fn-cluster-boot
print_a_function_from_file("cluster_boot")
```
### Section 1 — Average Treatment Effects {#sec-section-1}
**ATE recovery.** For each intervention, the average treatment effect (ATE) is the difference in mean outcome between participants assigned to that intervention and those in the control condition. ATEs are estimated with `run_main_treatment_model()`, run on the human reference and on the submission separately for each preregistered outcome. For the binary `newsletter_signup`, `run_main_treatment_model_binary()` returns marginal effects on the probability scale. Before any cross-outcome scoring, every estimate and standard error is converted to percentage points of its outcome's scale range (see [*Scoring principle*](#sec-scoring-principle)), so effects on the 0–100 sliders, the $0–10 donation, and the signup probability have comparable units. The comparison metrics (`pooled_metrics()`) and the calibration regression (`run_calibration_pooled()`) are then applied. The main analysis pools across all outcomes to maximize power.
### Section 2 — Subgroup Effects {#sec-section-2}
**Heterogeneity in treatment effects.** Interventions may work differently across demographic groups. A consensus message might shift trust more among Republicans than Democrats, or more among younger than older respondents. For each of six categorical moderators (gender, age band, race, education, income, partisan identity), condition × moderator interactions are estimated with `run_moderator_model()` on the human reference and on the submission. For the binary outcome the same OLS fit is a linear probability model, so the interaction coefficient is the difference-in-differences of cell signup proportions on the probability scale (see [*Estimation functions*](#sec-estimation-functions)). Each interaction estimate is a contrast against a reference level, and the reference levels are fixed here: the control condition for `condition`, and for each moderator its first codebook level^[The level order of the cleaned human data, which every submission's factors are aligned to before fitting — see `align_submission_levels()` under [*Placeholder data*](#sec-demo).]. As in [Section 1](#sec-section-1), all interaction estimates are converted to percentage points of each outcome's scale range before pooling. The interaction estimates are then compared with the same metrics as [Section 1](#sec-section-1), except RMSE: directional agreement, Spearman $\rho$, and Pearson r (`signed_metrics()`), plus the adjusted correlation r~adj~ computed from the human interaction estimates' standard errors. RMSE is left out. Interaction estimates come from small demographic cells and therefore carry far more sampling noise than ATEs, so the absolute distance between a prediction and the human estimate would mostly reflect noise in the human estimate itself rather than prediction quality. The same small cells make the reference noise large and uneven across groups, so raw correlations are unevenly deflated (see [*Adjusted correlation and RMSE (noise-corrected)*](#sec-adjusted-metrics)). The noise correction therefore matters more in this section than anywhere else in the benchmark, and r~adj~ is reported beside the raw correlation throughout the subgroup analyses. One limitation: the r~adj~ correction assumes that the sampling errors of the human estimates are independent of each other. For the interaction estimates this is not exactly true, because estimates for the same moderator share the reference group's cells, so their errors are correlated. The subgroup r~adj~ is therefore only an approximate correction here.
The subgroup effects analysis is only informative if the human data contain real moderation. If the true interaction effects are close to zero, every submission's correlation with these estimates is pushed toward zero. In such a case, the estimated true variance of the reference interactions can reach zero, in which case r~adj~ is undefined (see [*Adjusted correlation and RMSE (noise-corrected)*](#sec-adjusted-metrics)), and a submission that predicts no heterogeneity at all can hardly be beaten by a more accurate approach that predicts correctly whatever little heterogeneity there is.
### Section 3 — Baseline Calibration {#sec-section-3}
[Sections 1](#sec-section-1) [and 2](#sec-section-2) test whether an approach recovers treatment effects. [Section 3](#sec-section-3) asks a separate question: Does the synthetic sample match the human sample, any treatment effects aside? All comparisons in this section are run on the sample in the control condition, with one exception: the predictability regressions are run on the entire sample, while holding treatment effects constant with condition fixed effects.
**Response distributions.** Even an approach that matches every human ATE exactly may have different response distributions to begin with. Groups can differ in their means, but also in spread, skewness, or tail shape of the distributions. In the control condition, across all continuous outcomes^[`newsletter_signup` is excluded, since it is a binary outcome.], we therefore report each sample's mean beside the human one as the plain level check, and compare the full response distribution (`compare_distributions()`, reporting the variance ratio, OVL, KS D, and W1). The **variance ratio** is the headline diagnostic of the four, because under-dispersion (synthetic respondents answering too much alike, ratio < 1) is a widely reported issue in the recent synthetic sampling literature [@ashokkumarLargeLanguageModels2026a; @cumminsThreatAnalyticFlexibility2025b; @parkLLMAgentsGrounded2026; @arrudaCollectiveCooperationIndividual2026]. This analysis requires respondent-level data and so is Tier 1 only.
**Response distributions by subgroup.** Mirroring the overall comparison above, within each demographic subgroup in the control condition we compare response distributions (variance ratio, OVL, KS D, W1), to catch an approach that reproduces the overall distribution while miscalibrating within-group spreads. Groups under 30 respondents on either side are skipped, the same threshold as the demographic parity gap, and the skipped groups are named in the output. Tier 1 only.
**Demographic baseline calibration.** For each moderator, `compare_demographic_baselines()` computes each group's mean outcome in the control condition (say, mean trust among Republicans), separately for the human reference and for the submission, and reports the RMSE across the paired group means. A low RMSE means the approach starts from the right response level for each demographic group.^[Note that we do not report correlations here, because the units of analysis are the levels of the moderator variables. Since they have few levels (three to six) correlations would be unstable.] This is a different question from the distribution comparisons above: those ask whether the whole response distribution has the right shape and spread, while baseline calibration asks whether each group's *mean* sits at the right level. An approach can match every group mean while badly missing the spread within groups, and vice versa. Eligible for Tiers 1–2.
**Demographic parity gap (DPD).** The baseline-calibration metrics average over groups, and an average can hide a simulation approach that may serve most groups well while consistently missing one. Following the demographic-parity-difference summary of @parkLLMAgentsGrounded2026^[Park et al. compute the gap in per-group predictive accuracy over paired agent–person data, while this benchmark has no person-level pairing, so the gap is taken over group-mean baseline errors instead.], `demographic_parity_gap()` reports, per moderator, the gap between the worst- and best-served demographic group (the difference between the largest and smallest absolute cell-mean error in the control condition), together with which groups those are. The worst-served group's absolute error is reported alongside it, because a zero gap can also mean every group is served equally *badly*, which the worst-group error would reveal. Groups with fewer than 30 respondents on either side are skipped (`min_n = 30`), because a group mean over fewer respondents is itself several scale points of noise — and because the smallest groups are exactly the population this metric exists for, the skipped groups are named, with their sizes, in every table that reports the gap. Eligible for Tiers 1–2. For Tier 2, the submitted moderator-cell means take the place of computed group means.
**Demographic predictability and stereotyping.** For each of the six moderators we fit a separate OLS regression of the outcome on that moderator plus condition fixed effects, on the human reference and on the submission independently (`compare_demographic_predictability()`). The **dummy-coded coefficients are the primary stereotyping metric**: each coefficient is a group's gap to the moderator's reference level (say, how many points Democrats differ from Republicans, the reference level of partisan identity). Comparing a synthetic sample's gaps with the gaps in the human sample tests directly whether the approach exaggerates group differences. We will also report the **$R^2$ comparison**, which answers how much of the outcome variance the moderator explains in the synthetic sample versus in humans. The problem with this metric is that its interpretation is more ambiguous: A higher synthetic $R^2$ can be due to exaggerated group gaps or due to synthetic individuals answering too much alike (a smaller residual variance inflates $R^2$ even when every group mean is exactly right). We can tell these two sources apart via the regression coefficients and the variance ratio (above). Tier 1 only.
## Presentation of findings {#sec-findings}
[]{#sec-demo}
::: {.callout-note}
## Placeholder data
To illustrate how we intend to present results, we use random noise placeholder data, simulating **30 mock submissions from 26 mock "teams"**. All of this placeholder data is built in the simulation script (`R/simulate_data_preregistration.R`).
Some demonstration chunks below run on a reduced set of four outcome variables (`outcomes_illustrative` in the code underlying this preregistration). This subset exists only to keep this document fast to render. They are not part of the registered design: with real submissions, every analysis runs on all outcomes (except when explicitly stated otherwise, e.g., some analyses that only run on continuous outcomes).
:::
**Presentation.** Every preregistered metric is computed and reported. However, for the key figures of the manuscript, we will pick one key metric per question. **Pearson *r*** is the key metric for ATE recovery ([Section 1](#sec-section-1)) and, on the same axis, for subgroup recovery (Section 2). The calibration slope $\beta$ and intercept $\alpha$ answer whether those effects are the right size. The **variance ratio** is the key metric for the response-distribution analyses of [Section 3](#sec-section-3). Every other preregistered metric (directional agreement, Spearman $\rho$, the adjusted correlations, RMSE, OVL, KS, W1) is still computed and scored for every submission, and reported in a companion table.
The headline display (@fig-headline) puts the key measures in one figure with two panels. Panel A plots predicted against human ATEs across all approaches and outcomes, in percentage points of each outcome's scale range. It is overlaid with the average field and human calibration regressions. Panel B ranks the approaches on the pooled Pearson *r*, each with a cluster-bootstrap uncertainty interval over interventions. The human replication reference is pinned on top, and an all-approaches summary row at the bottom. The top and bottom 10% of entries are marked in the display: their rows are shaded in panel B, and their average calibration regressions are added to panel A. Entries are ordered by the pooled Pearson *r*, ties broken by pooled RMSE (smaller wins), remaining ties alphabetically by submission label. The order is based on observed scores, and observed scores are noisy. Two diagnostics aim to quantify that noise, both reuse the cluster bootstrap intervals. First, we take the entries that form the observed top 10% and treat them as a fixed set.^[Selecting a fresh top 10% within each replicate instead would always average the luckiest entries of that replicate and overstate the group's score.] In every bootstrap replicate (every redraw of interventions) we compute the average score of this set of entries. Across replicates, this gives the fixed group's mean score and its uncertainty interval. Second, we let every bootstrap replicate select its own top 10%, and count how often the entries in the observed set keep their place. If the same entries come out on top in nearly all replicates, the selection is stable. If membership changes a lot, the observed top group is a noisy draw from a field of near-ties. Both diagnostics are reported in @tbl-topk-stability.
Three further figures break the key metrics down, by outcome and by intervention (@fig-field-by-group), by moderator for subgroup recovery (@fig-subgroup-headline), and as per-outcome response densities with the variance ratio and Wasserstein-1 distance reported (@fig-distribution-headline).
```{r}
#| label: variables
outcomes_primary   <- "trust_multidimensional"
outcomes_secondary <- c("trust_post", "distrust_post",
                         "funding_perceptions", "policy_role_mean", "inst_trust_mean")
outcomes_tertiary  <- c("belief_post", "concern_mean", "policy_general",
                        "policy_specific_mean", "behavior_mean")
outcomes_continuous <- c(outcomes_primary, outcomes_secondary, outcomes_tertiary)

# The two behavioral outcomes enter the pooled cross-team metrics alongside
# the 0-100 sliders: donation in dollars via the
# OLS model, newsletter signup via logistic marginal effects on the
# probability scale. The by-intervention breakdown stays on
# `outcomes_continuous` only.
outcomes_behavioral <- c("donation_ams", "newsletter_signup")
outcomes_pooled     <- c(outcomes_continuous, outcomes_behavioral)

# The distribution analyses run on all continuous outcomes: the 11 sliders
# plus the donation (newsletter_signup is excluded as binary — a KDE is not
# meaningful there). W1 stays in each outcome's own scale units and is only
# ever reported per outcome.
outcomes_distribution <- c(outcomes_continuous, "donation_ams")

# Outcome classes for the secondary self-report vs behavioral cut (see
# "Where the field predicts well"): the 11 sliders are self-report attitude
# measures, the donation and the newsletter signup are behavior.
outcome_class <- c(
  set_names(rep("Self-report", length(outcomes_continuous)), outcomes_continuous),
  donation_ams = "Behavioral", newsletter_signup = "Behavioral"
)

# Expected pair count per submission: every scored intervention × every
# outcome (16 × 13 = 208 with the real data; the placeholder simulation
# generates 20 generic interventions, so this demo grid is 20 × 13). Every
# pair-building join asserts this count, so a mislabeled or missing condition
# or outcome stops the pipeline instead of silently shrinking a submission's
# test set.
n_pairs_expected <- (length(scored_conditions) - 1) * length(outcomes_pooled)

# Scale ranges: all cross-team scoring runs in percentage points (pp) of each
# outcome's scale range — effects and SEs are converted once, at pair-building
# time, and every downstream metric, figure, and table reads the same unit.
# This follows Ashokkumar et al.'s primary archive, which pools effects only
# after expressing them in pp of the original scales, and deliberately avoids
# SD standardization (an under-dispersed submission would corrupt an SD
# denominator). Pooling raw mixed units instead would let the 0-100 sliders
# drown out the two behavioral outcomes (dollar and probability effects are
# 10-100x smaller numerically) and hand every submission 32 free near-origin
# points. The 0-100 sliders are already in pp; only the donation (0-10
# dollars) and signup probability (0-1) rescale.
scale_range <- c(
  set_names(rep(100, length(outcomes_continuous)), outcomes_continuous),
  donation_ams = 10, newsletter_signup = 1
)

# Bootstrap replicates: the PREREGISTERED value for the real-data run is
# 2,000. This placeholder render is a demonstration of the procedure, not of
# its precision, so it uses a small demo value to keep the render cheap —
# only this parameter changes when the submissions arrive, nothing else.
n_boot_real <- 2000
n_boot_demo <- 200

# Resplit sensitivity check (see "Robustness of the scoring pipeline"): same
# demo/real split as the bootstrap. The PREREGISTERED value for the real-data
# run is 200 resplits; the placeholder render uses 50 to keep the build cheap.
n_resplit_real <- 200
n_resplit_demo <- 50

# Demo-only outcome subset (see the Placeholder data callout under Presentation of findings):
# the subgroup demo below runs these four outcomes plus the binary newsletter
# signup to keep the moderator-model fits fast in this render. The
# registered subgroup analysis runs all outcomes. The newsletter interaction
# difference-in-differences come from the linear probability model, so they
# live on the probability scale and pp-rescale like everything else.
outcomes_illustrative <- c("trust_multidimensional", "donation_ams",
                           "funding_perceptions", "policy_general")
outcomes_subgroup     <- c(outcomes_illustrative, "newsletter_signup")
moderators_cat <- c("gender", "age_band", "race", "education", "income", "party")

outcome_label_map <- c(
  trust_multidimensional = "Multidimensional trust (primary)",
  trust_post             = "Single-item trust",
  distrust_post          = "Distrust",
  funding_perceptions    = "Funding perceptions",
  policy_role_mean       = "Policy role",
  inst_trust_mean        = "Institutional trust",
  belief_post            = "Climate belief",
  concern_mean           = "Climate concern",
  policy_general         = "General climate policy",
  policy_specific_mean   = "Specific climate policy",
  behavior_mean          = "Pro-climate behavior",
  donation_ams           = "Donation to AMS ($)",
  newsletter_signup      = "Newsletter signup"
)
```
```{r}
#| label: leaderboard-helpers
# Extract ATE pairs (estimate, SE) — as in the original preregistration's
# rq1-all chunk, minus the adjusted p-value: no benchmark metric reads it
# (the significance-based metrics were dropped), so the
# pairs no longer carry it.
prep_ate <- function(df) {
  df |>
    select(condition, estimate) |>
    mutate(se = if ("std.error" %in% names(df)) df$std.error else NA_real_)
}

control_lab <- levels(human_data$condition)[1]
z95 <- qnorm(0.975)

# Submitted CSVs arrive with character columns, and the estimation functions
# take the first factor level as the reference (control for condition, the
# first codebook level for each moderator). Alphabetical coercion would pick
# the wrong reference — capitalized condition titles sort before "control",
# "Bachelor's degree" before "Less than high school" — so the level order
# of every individual-level submission is set to match the human reference
# data before fitting.
align_submission_levels <- function(dat) {
  dat |>
    mutate(
      condition = fct_relevel(factor(condition), control_lab),
      across(any_of(moderators_cat),
             ~ fct_relevel(factor(.x),
                           intersect(levels(human_data_1[[cur_column()]]),
                                     unique(as.character(.x)))))
    )
}

# Reference (Human 1) ATE models on the continuous outcomes, fit once and
# reused.
human_models <- map(outcomes_continuous,
                    ~ run_main_treatment_model(human_data_1, outcome = .x)) |>
  set_names(outcomes_continuous)

# One ATE side (estimate, SE, BH-adjusted p) for an individual-level dataset,
# across all pooled outcomes: OLS with HC2 SEs for the continuous outcomes and
# the donation; logistic marginal effects on the probability scale for the
# binary newsletter signup. The binary SE is recovered
# from the marginal-effect CI.
ate_side <- function(dat, models = NULL) {
  cont <- map_dfr(c(outcomes_continuous, "donation_ams"), function(out) {
    res <- if (!is.null(models) && out %in% names(models)) models[[out]]
           else run_main_treatment_model(dat, outcome = out)
    prep_ate(res) |> mutate(outcome = out)
  })
  bin <- run_main_treatment_model_binary(dat,
                                         outcome = "newsletter_signup")$marginal_effects |>
    transmute(condition,
              estimate,
              se      = (conf.high - conf.low) / (2 * z95),
              outcome = "newsletter_signup")
  bind_rows(cont, bin)
}

human_side <- ate_side(human_data_1, models = human_models) |>
  rename(estimate_h = estimate, se_h = se)

# The reference side must itself span the full scored grid before any
# submission is joined against it.
stopifnot(nrow(human_side) == n_pairs_expected)

# Inner joins drop unmatched rows silently, so a mislabeled condition or
# outcome in a submission would quietly shrink its test set and its scores
# would be computed on the surviving subset. Every pair builder therefore
# asserts the full scored grid, with no missing estimates — a submission that
# cannot be paired completely stops the pipeline instead of being scored
# partially.
assert_full_grid <- function(pairs) {
  stopifnot(nrow(pairs) == n_pairs_expected,
            !anyNA(pairs$estimate_l), !anyNA(pairs$estimate_h))
  pairs
}

# Common unit for all scoring: estimates and SEs in pp of each outcome's scale
# range (see `scale_range` in the variables chunk). Applied once to every set
# of joined pairs — the three tier builders, the floor baseline, and the
# subgroup pairs — so all pooled metrics, figures, and tables read one unit.
# A positive multiplicative factor: signs and p-values are untouched.
pp_scale_pairs <- function(pairs) {
  pairs |>
    mutate(across(any_of(c("estimate_h", "se_h", "estimate_l", "se_l")),
                  ~ .x * 100 / scale_range[outcome]))
}

# Tier 1: ATE pairs from an individual-level dataset, refitting the
# preregistered treatment models on the submission. The refit SE travels with
# the pairs as se_l: it measures the submission's own sampling noise, which
# the corrected calibration slope needs (see run_calibration_pooled()).
build_pairs_t1 <- function(pred_data) {
  ate_side(align_submission_levels(pred_data)) |>
    select(condition, outcome, estimate_l = estimate, se_l = se) |>
    inner_join(human_side, by = c("condition", "outcome")) |>
    pp_scale_pairs() |>
    assert_full_grid()
}

# Tier 2: ATEs from submitted cell means (mean per condition x outcome),
# treatment cell minus control cell.
build_pairs_t2 <- function(cells_main) {
  cells_main |>
    mutate(condition = as.character(condition)) |>
    group_by(outcome) |>
    group_modify(function(cells, key) {
      ctrl <- cells |> filter(condition == control_lab)
      cells |>
        filter(condition != control_lab) |>
        transmute(condition, estimate_l = mean - ctrl$mean)
    }) |>
    ungroup() |>
    inner_join(human_side, by = c("condition", "outcome")) |>
    pp_scale_pairs() |>
    assert_full_grid()
}

# Tier 3: submitted ATEs taken as-is.
build_pairs_t3 <- function(effects) {
  effects |>
    transmute(condition = as.character(condition), outcome, estimate_l = ate) |>
    inner_join(human_side, by = c("condition", "outcome")) |>
    pp_scale_pairs() |>
    assert_full_grid()
}

# `pooled_metrics()`, `signed_metrics()`, and `cluster_boot()` are defined in
# R/functions/statistics.R and shown under "Scoring functions" above.

# One leaderboard row: pooled metrics + the intercept and slope of the pooled
# calibration regression (all outcomes; descriptive; 95% intervals come from
# the intervention cluster bootstrap in the leaderboard-build chunk below).
# beta_adj is the noise-corrected slope, computable only for Tier 1 (the
# refit SEs se_l exist there); it is NA for Tiers 2-3 and the reference rows.
# No usable-share column: assert_full_grid() makes partially paired
# submissions impossible, so every scored row rests on the full grid.
leaderboard_row <- function(pairs, submission, tier, disclosure) {
  calib <- run_calibration_pooled(pairs)
  pooled_metrics(pairs, include_rmse = TRUE) |>
    mutate(submission = submission, tier = tier, disclosure = disclosure,
           alpha = calib$alpha, beta = calib$beta, beta_adj = calib$beta_adj)
}
```
```{r}
#| label: mock-submissions
# Mock Tier 2 (cell-level) and Tier 3 (effect-level) submissions, generated
# outside this script alongside the other placeholder data (see
# R/simulate_data_preregistration.R) so that no mock-data simulation lives in
# the preregistration document. Tier 2 collapses one placeholder team to the
# cell-level schema (*_cells_main.csv); Tier 3 gives ATEs vs. control.
cells_t2   <- readRDS(here("data/simulation_preregistration/mock_submission_tier2_cells.rds"))
effects_t3 <- readRDS(here("data/simulation_preregistration/mock_submission_tier3_effects.rds"))
```
```{r}
#| label: leaderboard-build
# 30 mock entries plus the fixed human replication reference (Human 1 vs. Human 2).
# Entries 1-28 are individual-level Tier 1 data; entry 29 is a Tier 2
# cell-level file and entry 30 a Tier 3 effect-level file, so all three tier
# code paths are exercised. Each entry's ATE pairs are built once here and
# reused by the headline and breakdown figures, the leaderboard table, and the
# companion tables. The cached lists are keyed by the sim's entry ids
# ("Team N"); display labels are applied right after via submission_meta.
tier1_ids <- 1:28

# Cached: the 29 Tier-1 builds each refit the treatment models incl. the
# logistic marginal effects for the newsletter outcome, the slow step of a
# cold render.
pairs_list <- cached("amendment_pairs_list", {
  c(
    set_names(
      map(tier1_ids,
          ~ build_pairs_t1(llm_data_teams |> filter(team == paste0("team_", .x)))),
      paste0("Team ", tier1_ids)
    ),
    list(
      "Team 29"           = build_pairs_t2(cells_t2),
      "Team 30"           = build_pairs_t3(effects_t3),
      "Human replication" = build_pairs_t1(human_data_2)
    )
  )
})

# Mock team structure for the entry policy (see Presentation of findings): the 30 mock
# entries belong to 26 mock teams. Teams 1 and 2 hold three Tier-1 entries
# each (the _a entry is the team's primary), teams 3-24 one Tier-1 entry,
# team 25 the Tier-2 entry, team 26 the Tier-3 entry. Everything downstream
# shows the neutral submission labels; @tbl-submission-teams maps labels to
# teams.
set.seed(2026)
submission_meta <- tibble(
  entry_id   = c(paste0("Team ", 1:30), "Human replication"),
  team       = c(rep(c("Mock team 1", "Mock team 2"), each = 3),
                 paste("Mock team", 3:26), "Human replication"),
  entry      = c(rep(c("primary", "secondary-1", "secondary-2"), times = 2),
                 rep("primary", 24), "—"),
  submission = c(paste0("submission_1_", letters[1:3]),
                 paste0("submission_2_", letters[1:3]),
                 paste0("submission_", 3:26), "Human replication"),
  tier       = c(rep("1", 28), "2", "3", "—"),
  disclosure = c(sample(c("A", "B", "C"), 30, replace = TRUE), "—")
)

relabel_submissions <- function(x)
  set_names(x, submission_meta$submission[match(names(x), submission_meta$entry_id)])

# Same mapping for data frames that carry a submission column (the cached
# bootstrap results stamp it at cache time, possibly under the entry ids);
# labels already in display form pass through unchanged.
relabel_submission_col <- function(df) {
  lookup <- set_names(submission_meta$submission, submission_meta$entry_id)
  df |> mutate(submission = coalesce(unname(lookup[submission]), submission))
}

pairs_list <- relabel_submissions(pairs_list)

# Floor baseline: a naive reference row for the metrics without a natural
# null (chiefly RMSE). "No effect" predicts a zero ATE everywhere — a fully
# naive, blinded-achievable strategy. It is a reference row like the human
# replication, not a member of the field: excluded from the field violins and
# the field summary. (An oracle-mean floor — predict each outcome's mean human
# ATE everywhere — was considered and rejected: the mean is the in-sample
# least-squares constant fit to the very ATEs being scored, so it competes
# rather than floors; its interpretive content survives as the RMSE scale
# reference, the SD of the human ATEs.)
floor_pairs <- list(
  "Floor: no effect" = human_side |>
    mutate(estimate_l = 0) |>
    pp_scale_pairs(),
  # The all-positive baseline exists because 50% is the wrong chance level
  # for directional agreement when the interventions were all designed to
  # increase trust: a mindless "every message works" strategy scores the
  # share of positive human ATEs, and that share — this row's directional
  # % — is the empirical chance level the field has to beat.
  "Floor: all positive" = human_side |>
    mutate(estimate_l = 1) |>
    pp_scale_pairs()
)
floor_labels <- names(floor_pairs)

# Calibration is undefined for the floors (a constant prediction ->
# zero-variance regressor), so their rows carry NA there. Under the
# half-credit rule the no-effect floor's directional % reads 50, a predictor
# with no directional information. The all-positive row reports its
# directional % only: its other scores are artifacts of a constant
# prediction and are not shown.
floor_rows <- imap_dfr(floor_pairs, function(pr, sub) {
  row <- pooled_metrics(pr, include_rmse = TRUE) |>
    mutate(submission = sub, tier = "—", disclosure = "—",
           alpha = NA_real_, beta = NA_real_, beta_adj = NA_real_)
  if (sub == "Floor: all positive")
    row <- row |>
      mutate(across(c(spearman_rho, pearson_r, pearson_within, pearson_adj,
                      rmse, rmse_adj), ~ NA_real_),
             rmse_adj_at_floor = NA)
  row
})

# Wisdom-of-crowds ensemble: the field's average prediction, scored as one
# extra pseudo-submission. Within each intervention × outcome pair, the mean
# predicted ATE across all entries (the human replication excluded); the
# pairs are already in pp of scale range, so the mean is taken in the common
# unit. Errors that point in different directions on the same pair cancel in
# this within-pair mean, so the ensemble's scores can beat every single
# entry's — the size of that gap measures how independent the entries' errors
# are. A non-competing reference row like the human replication and the
# floors: it appears on the leaderboard and is excluded from every field
# summary, because it is not a member of the field but the field averaged.
# Its submission-side SE is undefined (an average of point predictions), so
# the metrics needing se_l stay NA, as for Tiers 2-3.
ensemble_label <- "Wisdom of crowds"
ensemble_pairs <- imap_dfr(pairs_list, ~ mutate(.x, submission = .y)) |>
  filter(submission != "Human replication") |>
  group_by(condition, outcome) |>
  summarise(estimate_l = mean(estimate_l),
            estimate_h = first(estimate_h),
            se_h       = first(se_h),
            .groups    = "drop") |>
  mutate(se_l = NA_real_)

leaderboard <- bind_rows(
  imap_dfr(pairs_list, function(pr, sub) {
    m <- submission_meta |> filter(submission == sub)
    leaderboard_row(pr, sub, tier = m$tier, disclosure = m$disclosure)
  }),
  leaderboard_row(ensemble_pairs, ensemble_label,
                  tier = "—", disclosure = "—"),
  floor_rows
) |>
  arrange(desc(submission == "Human replication"), desc(pearson_r))

# 95% intervals for the calibration coefficients, from the same intervention
# cluster bootstrap (identical seed and draws) as every other metric. The 13
# outcomes within an intervention share that intervention's draw, and
# resampling interventions whole respects that dependence — this replaces the
# HC2 intervals, which treated the pooled pairs as independent. The shared
# control arm stays fixed across replicates (see the caveats under
# "Uncertainty intervals on the leaderboard"). Fast enough to run uncached.
calib_ci <- imap_dfr(c(pairs_list, set_names(list(ensemble_pairs), ensemble_label)),
                     function(pr, sub) {
  cluster_boot(pr, run_calibration_pooled, n_boot = n_boot_demo) |>
    mutate(submission = sub)
}) |>
  filter(metric %in% c("alpha", "beta")) |>
  pivot_wider(names_from = metric, values_from = c(value, lo, hi),
              names_glue = "{metric}_{.value}") |>
  select(submission, alpha_lo = alpha_lo, alpha_hi = alpha_hi,
         beta_lo = beta_lo, beta_hi = beta_hi)
```
```{r}
#| label: ate-ladder-labels
# Display labels / panel order for the metrics.
ladder_labels <- c(
  directional_pct = "Directional %",
  spearman_rho    = "Spearman ρ",
  pearson_r       = "Pearson r",
  pearson_within  = "Pearson r (within outcomes)",
  pearson_adj     = "Pearson r (adj.)",
  rmse            = "RMSE (pp)",
  rmse_adj        = "RMSE (adj., pp)"
)
relabel_metrics <- function(df, labels) {
  df |> mutate(metric = factor(labels[metric], levels = labels))
}
```
### Finding 1 — How well can the field predict the experiment? {#sec-finding-1}
@fig-headline shows the raw prediction task with the field's calibration lines and coefficients (A) and the ranking of the field on the pooled Pearson *r* (B).^[One rendering note on panel B. This placeholder demonstration runs the bootstrap with a small replicate count (`n_boot_demo = 200`) to keep the document cheap to build. The preregistered value for the real-data run is `n_boot_real = 2,000`.] @tbl-field-summary provides a summary of the field's distribution for additional evaluation metrics.
```{r}
#| label: fig-headline
#| fig-width: 12
#| fig-height: 8
#| fig-cap: "Headline cross-team figure (placeholder data). (A) Predicted against human ATEs across all outcomes and approaches, in percentage points of each outcome's scale range (as in the predicted-vs-observed figure of Ashokkumar et al.), one point per approach × intervention × outcome. Axes are centered on zero, the dashed line is the identity, and red crosses mark the human replication reference (Human 2 predicting Human 1). The solid lines are the average calibration regression of human on predicted ATEs, pooled across all outcomes, dark blue for the field (per-approach fits averaged) and red for the human replication reference. The grey dashed lines are the same per-approach-fits-averaged regressions for the top and bottom 10% of the ranking in B. The corner prints, for each of the four, the (mean) Pearson r with its noise-corrected value where defined — the same pooled metric ranked in B — and the calibration coefficients (slope β, perfect = 1, and intercept α, perfect = 0) with 95% CIs. (B) Approaches ranked by Pearson r pooled across all outcomes against Human 1. Filled points carry 95% cluster-bootstrap intervals over interventions, open points show the noise-corrected r (adj.) where its guard allows a value, and the human replication reference is pinned on top with its value dropped as a dotted line. The shaded bands mark the top and bottom 10% of entries (selection rule in the text). The bottom row summarizes the field, with the density of the approaches' scores, a diamond at their mean with its 95% CI, and an open point at the mean noise-corrected r. On placeholder data every approach is a noise resample of the same dataset, so the field clusters near r = 0 in panel B, as expected of a random resample."
# (A) the raw prediction task: all approaches, all outcomes. The pairs are
# already in pp of scale range (pp_scale_pairs() at pair-building), the same
# unit as every pooled metric.
headline_pairs <- imap_dfr(pairs_list, ~ mutate(.x, submission = .y))
p_scatter <- plot_pred_scatter(
  headline_pairs,
  x_lab       = "Predicted ATE (pp of scale range)",
  y_lab       = "Human ATE (pp of scale range)",
  tag         = "A",
  point_alpha = 0.15, point_size = 0.5,
  ref_alpha   = 0.6,  ref_size   = 1,
  symmetric   = TRUE
)

# Registered selection rule for the extreme groups: entries ordered by the
# pooled Pearson r, ties broken by pooled RMSE (smaller wins), remaining ties
# alphabetically by submission label; the top and bottom groups are the first
# and last k = ceiling(0.10 × n entries) of that order.
field_ranked <- leaderboard |>
  filter(submission != "Human replication", submission != ensemble_label,
         !submission %in% floor_labels) |>
  arrange(desc(pearson_r), rmse, submission)
k_extreme   <- ceiling(0.10 * nrow(field_ranked))
top_subs    <- field_ranked |> slice_head(n = k_extreme) |> pull(submission)
bottom_subs <- field_ranked |> slice_tail(n = k_extreme) |> pull(submission)

# Average field / human calibration lines + a corner readout of correlation
# (r, adj.) and coefficients (β, α with CI), plus the same for the top and
# bottom 10%. Mean Pearson r values and their noise-corrected companions come
# from the pooled leaderboard — the identical pp quantity ranked in panel B;
# the coefficients are fit from the same pp pairs by calibration_overlay().
field_ld  <- leaderboard |> filter(!submission %in% floor_labels,
                                   submission != "Human replication",
                                   submission != ensemble_label)
human_ld  <- leaderboard |> filter(submission == "Human replication")
top_ld    <- leaderboard |> filter(submission %in% top_subs)
bottom_ld <- leaderboard |> filter(submission %in% bottom_subs)
p_scatter <- p_scatter +
  calibration_overlay(headline_pairs,
                      r_field       = mean(field_ld$pearson_r,   na.rm = TRUE),
                      radj_field    = mean(field_ld$pearson_adj, na.rm = TRUE),
                      r_human       = human_ld$pearson_r,
                      radj_human    = human_ld$pearson_adj,
                      top_labels    = top_subs,
                      bottom_labels = bottom_subs,
                      r_top         = mean(top_ld$pearson_r,       na.rm = TRUE),
                      radj_top      = mean(top_ld$pearson_adj,     na.rm = TRUE),
                      r_bottom      = mean(bottom_ld$pearson_r,    na.rm = TRUE),
                      radj_bottom   = mean(bottom_ld$pearson_adj,  na.rm = TRUE))

# (B) ranked field on the key metric, with cluster-bootstrap intervals.
# n_boot_demo here; the real-data run uses n_boot_real = 2,000 (see variables).
pooled_f <- \(p) pooled_metrics(p)
ate_forest <- cached("amendment_ate_forest", {
  imap_dfr(pairs_list, function(pr, sub) {
    cluster_boot(pr, pooled_f, cluster = "condition", n_boot = n_boot_demo) |>
      mutate(submission = sub)
  }) |>
    relabel_metrics(ladder_labels)
}) |>
  relabel_submission_col()
p_forest <- plot_field_forest_single(
  ate_forest,
  highlight_top    = top_subs,
  highlight_bottom = bottom_subs,
  rank_order       = rev(field_ranked$submission),
  tag              = "B"
)

(p_scatter | p_forest) + plot_layout(widths = c(1, 1.15))
```
```{r}
#| label: topk-stability
# Selection diagnostics for the extreme groups. cluster_boot() seeds every
# submission's bootstrap identically (seed 2026 before the replicate loop, the
# same cluster names in the same order), so replicate b resamples the same
# interventions for every submission — a shared bootstrap. Recomputing with
# one shared draw per replicate reproduces those draws and yields the full
# field's pooled r per replicate, the basis for the top-group diagnostics.
topk_boot <- cached("amendment_topk_stability", {
  sub_parts <- map(pairs_list[field_ranked$submission],
                   ~ split(.x, as.character(.x$condition)))
  cl_names  <- names(sub_parts[[1]])
  set.seed(2026)
  map_dfr(seq_len(n_boot_demo), function(b) {
    drawn <- sample(cl_names, length(cl_names), replace = TRUE)
    imap_dfr(sub_parts, function(parts, sub)
      tibble(replicate  = b,
             submission = sub,
             pearson_r  = pooled_metrics(bind_rows(parts[drawn]))$pearson_r))
  })
})

# Membership stability: which entries make the top group in each replicate
# (within replicates, ties broken alphabetically — RMSE is not recomputed
# per replicate).
rep_top <- topk_boot |>
  group_by(replicate) |>
  arrange(desc(pearson_r), submission, .by_group = TRUE) |>
  slice_head(n = k_extreme) |>
  summarise(members = list(submission), .groups = "drop")

top_overlap <- map_dbl(rep_top$members,
                       ~ length(intersect(.x, top_subs)) / k_extreme)

# The fixed observed top group, rescored across replicates: its mean pooled r
# with a percentile interval.
fixed_top <- topk_boot |>
  filter(submission %in% top_subs) |>
  group_by(replicate) |>
  summarise(mean_r = mean(pearson_r), .groups = "drop") |>
  pull(mean_r)

top_stability <- tibble(
  intact_pct   = 100 * mean(top_overlap == 1),
  avg_retained = k_extreme * mean(top_overlap),
  fixed_mean   = mean(fixed_top),
  fixed_lo     = quantile(fixed_top, 0.025),
  fixed_hi     = quantile(fixed_top, 0.975)
)
```
```{r}
#| label: tbl-topk-stability
#| tbl-cap: "Selection diagnostics for the top group (placeholder data). The observed top 10% treated as a fixed set: its mean pooled Pearson r across the shared bootstrap replicates with a 95% percentile interval. Membership stability lets each replicate select its own top group: the share of replicates in which the observed set stays fully intact, and the average number of its members retained. On placeholder data all entries are near-ties by construction, so membership is expected to be unstable."
top_stability |>
  mutate(fixed_ci     = sprintf("%.2f [%.2f, %.2f]",
                                fixed_mean, fixed_lo, fixed_hi),
         avg_retained = sprintf("%.1f of %d", avg_retained, k_extreme)) |>
  select(fixed_ci, intact_pct, avg_retained) |>
  gt() |>
  fmt_number(columns = intact_pct, decimals = 0) |>
  cols_label(fixed_ci     = "Fixed top group: mean r [95% CI]",
             intact_pct   = "Replicates fully intact (%)",
             avg_retained = "Avg. members retained")
```
```{r}
#| label: field-pooled-compute
field_pooled <- leaderboard |>
  # floors and the ensemble are reference rows, not field members
  filter(!submission %in% floor_labels, submission != ensemble_label) |>
  select(submission, all_of(names(ladder_labels))) |>
  pivot_longer(-submission, names_to = "metric", values_to = "value") |>
  relabel_metrics(ladder_labels)
```
```{r}
#| label: tbl-field-summary
#| tbl-cap: "Field summary (placeholder data). Center and spread of each pooled ATE-recovery metric across the 30 mock entries (the human replication reference excluded). Entries from the same team are not independent; the primaries-only recomputation is in @tbl-field-primaries."
summarise_field(field_pooled) |>
  gt() |>
  fmt_number(columns = c(mean, median, sd, min, max), decimals = 2) |>
  cols_label(metric = "Metric", mean = "Mean", median = "Median",
             sd = "SD", min = "Min", max = "Max")
```
#### Wisdom of crowds {#sec-wisdom-of-crowds}
For quantitative estimation tasks, the wisdom of crowds literature suggests that the average estimate of individuals outperforms the average individual's estimate [@larrickIntuitionsCombiningOpinions2006]. If the wisdom of crowds effect applied to synthetic sampling, it might be a better strategy for any research team to take the average of several different simulation pipelines, than aiming for one single best pipeline. To address this question, we add the field's **average prediction** as one extra, non-competing entry, labeled **Wisdom of crowds** in the tables.
The construction differs from the field summaries above in *where* the averaging happens. The field summary collapses over average submission scores *across* all outcome x intervention pairs: each submission's predictions are scored across outcome x intervention pairs into one pooled *r*, and these scores are then averaged across submissions. That number says how good the typical entry is. The Wisdom of crowds row collapses over submissions *within* outcome x intervention pairs: within each single intervention × outcome pair, the predicted ATEs of all submissions are averaged into one combined prediction, which is then scored into a pooled *r* like another submission. To illustrate the difference: If, for instance, one entry overshoots an effect by +3 pp and another undershoots it by −3 pp, the within-pair average (wisdom of the crowd) is exactly right. By contrast, the average performance of both approaches (field average) is off, as it summarizes the prediction score of two entries that were off. The gap between the wisdom of the crowd score and the field's average score therefore measures how independent the entries' errors are. If submissions err in their own independent, quite different ways, we would expect to find a wisdom of the crowd effect. If instead the field shares the same biases — say every LLM-based approach overshoots the same interventions — we would expect the "Wisdom of crowds" entry to land close to the average entry.
The "Wisdom of crowds" entry uses the unweighted mean across all entries. It appears as a marked, non-competing row in the leaderboard table. It does not appear in the ranking figure and does not enter the field summaries. It carries no standard error, so the noise-corrected slope stays NA as for Tiers 2–3.^[On the placeholder data the entries are independent noise resamples of one dataset, so cancellation is maximal by construction: the ensemble scores *r* = `r sprintf("%.2f", leaderboard |> filter(submission == ensemble_label) |> pull(pearson_r))`, against a field mean of `r sprintf("%.2f", mean(field_ld$pearson_r, na.rm = TRUE))` and a best single entry of `r sprintf("%.2f", max(field_ranked$pearson_r, na.rm = TRUE))`. With real submissions, correlated errors across teams would pull the ensemble back toward the field.]
The same logic applies within teams, where it answers a perhaps practically more relevant version of the question. A team with several entries is its own small crowd. For **every team with more than one entry**, we therefore also score the **within-team average** — within each intervention × outcome pair, the mean predicted ATE across all of the team's entries, its primary included — and compare it against the team's primary entry in @tbl-team-average. Like the field ensemble, the within-team averages are non-competing, appear only in this table, and carry no submission-side standard error. In the placeholder data, two mock teams hold three entries each.
```{r}
#| label: tbl-team-average
#| tbl-cap: "Within-team averages against primary entries (placeholder data). For each team with more than one entry, the pooled ATE-recovery metrics of the team's designated primary entry and of the within-team average (the mean predicted ATE across all of the team's entries, per intervention × outcome pair). On placeholder data the entries are noise resamples of one dataset, so the average is expected to score above the primary by construction."
multi_entry_teams <- submission_meta |>
  filter(submission != "Human replication") |>
  add_count(team) |>
  filter(n > 1)

team_average_rows <- multi_entry_teams |>
  distinct(team) |>
  pull(team) |>
  map_dfr(function(tm) {
    subs    <- multi_entry_teams |> filter(team == tm) |> pull(submission)
    primary <- multi_entry_teams |> filter(team == tm, entry == "primary") |>
      pull(submission)
    avg_pairs <- imap_dfr(pairs_list[subs], ~ mutate(.x, submission = .y)) |>
      group_by(condition, outcome) |>
      summarise(estimate_l = mean(estimate_l),
                estimate_h = first(estimate_h),
                se_h       = first(se_h),
                .groups    = "drop") |>
      mutate(se_l = NA_real_)
    bind_rows(
      leaderboard |>
        filter(submission == primary) |>
        select(directional_pct, spearman_rho, pearson_r, rmse) |>
        mutate(entry = paste0(primary, " (primary)")),
      pooled_metrics(avg_pairs, include_rmse = TRUE) |>
        select(directional_pct, spearman_rho, pearson_r, rmse) |>
        mutate(entry = paste0(str_remove(primary, "_a$"),
                              " (average of ", length(subs), " entries)"))
    )
  })

team_average_rows |>
  select(entry, directional_pct, spearman_rho, pearson_r, rmse) |>
  gt() |>
  fmt_number(columns = c(spearman_rho, pearson_r, rmse), decimals = 2) |>
  fmt_number(columns = directional_pct, decimals = 0) |>
  cols_label(entry = "", directional_pct = "Directional %",
             spearman_rho = "Spearman ρ", pearson_r = "Pearson r",
             rmse = "RMSE (pp)")
```
#### Where the field predicts well {#sec-field-by-group}
Split **by outcome** (one distribution per outcome, scored across the interventions) and **by intervention** (one per intervention, scored across the continuous outcomes, see [*Scoring principle*](#sec-scoring-principle)), the key metric shows *where* the field predicts well and what resists prediction (@fig-field-by-group). The full metrics per outcome and per intervention are in @tbl-field-by-outcome and @tbl-field-by-intervention.
```{r}
#| label: field-by-group-compute
# include_rmse: with all pairs in pp, RMSE and its noise-corrected companion
# RMSE_adj are defined per outcome and pooled alike; here they localise where
# the absolute error concentrates.
field_by_outcome <- imap_dfr(pairs_list, function(pr, sub) {
  metrics_by_group(pr, "outcome",
                   f = \(p) pooled_metrics(p, include_rmse = TRUE)) |>
    mutate(submission = sub)
}) |>
  mutate(outcome = factor(unname(outcome_label_map[outcome]),
                          levels = unname(outcome_label_map))) |>
  pivot_longer(c(directional_pct, spearman_rho, pearson_r, pearson_adj,
                 rmse, rmse_adj),
               names_to = "metric", values_to = "value") |>
  relabel_metrics(ladder_labels)

# Restricted to the 0-100 continuous outcomes: with pp units the scale
# confound is gone, but a per-intervention correlation across all 13 outcomes
# would still mix constructs (attitude sliders vs. behaviors), so the
# conservative restriction is kept. Within that restriction all pairs share
# one scale, so the full metric set incl. RMSE applies, same as by outcome.
field_by_intervention <- imap_dfr(pairs_list, function(pr, sub) {
  metrics_by_group(pr |> filter(outcome %in% outcomes_continuous), "condition",
                   f = \(p) pooled_metrics(p, include_rmse = TRUE)) |>
    mutate(submission = sub)
}) |>
  pivot_longer(c(directional_pct, spearman_rho, pearson_r, pearson_adj,
                 rmse, rmse_adj),
               names_to = "metric", values_to = "value") |>
  relabel_metrics(ladder_labels)

# Companion-table helper: field median per metric within each group level,
# with the human replication reference value in parentheses.
field_group_table <- function(field_long, group,
                              pct_metrics = "Directional %") {
  fmt <- function(v, pct) if_else(is.na(v), "—",
                                  if_else(pct, sprintf("%.0f", v),
                                          sprintf("%.2f", v)))
  med <- field_long |>
    filter(submission != "Human replication") |>
    group_by(across(all_of(group)), metric) |>
    summarise(med = median(value, na.rm = TRUE), .groups = "drop")
  ref <- field_long |>
    filter(submission == "Human replication") |>
    select(all_of(group), metric, ref = value)
  med |>
    left_join(ref, by = c(group, "metric")) |>
    mutate(pct  = metric %in% pct_metrics,
           cell = paste0(fmt(med, pct), " (", fmt(ref, pct), ")")) |>
    select(all_of(group), metric, cell) |>
    pivot_wider(names_from = metric, values_from = cell)
}
```
```{r}
#| label: fig-field-by-group
#| fig-width: 11
#| fig-height: 6.5
#| fig-cap: "Where the field predicts well (placeholder data). Distribution of each approach's Pearson r by outcome (A, scored across the interventions) and by intervention (B, scored across the continuous outcomes). One dot per approach over the field's half-violin, with the field mean and its 95% CI (white diamond) on each row. Red crosses mark the human replication reference, the dotted line the null."
by_outcome_r <- field_by_outcome |>
  filter(metric == "Pearson r") |>
  mutate(metric = factor("Outcomes"))
by_intervention_r <- field_by_intervention |>
  filter(metric == "Pearson r") |>
  mutate(metric = factor("Interventions"))

p_by_outcome <- plot_metric_distribution(
  by_outcome_r, x = "outcome", mean_ci = TRUE,
  ref_lines = c("Outcomes" = 0)
) + labs(tag = "A", y = "Pearson r")
p_by_intervention <- plot_metric_distribution(
  by_intervention_r, x = "condition", mean_ci = TRUE,
  ref_lines = c("Interventions" = 0)
) + labs(tag = "B", y = "Pearson r")

p_by_outcome | p_by_intervention
```
```{r}
#| label: tbl-field-by-outcome
#| tbl-cap: "Field summary by outcome (placeholder data). Median across approaches of each metric, scored per outcome across the interventions, with the human replication reference in parentheses. RMSE and RMSE (adj.) are in pp of scale range, the same unit as the pooled row. Per outcome they localize where the absolute error concentrates."
field_group_table(field_by_outcome, "outcome") |>
  gt() |>
  sub_missing(missing_text = "—") |>
  cols_label(outcome = "Outcome")
```
```{r}
#| label: tbl-field-by-intervention
#| tbl-cap: "Field summary by intervention (placeholder data). Median across approaches of each metric, scored per intervention across the continuous outcomes, with the human replication reference in parentheses. RMSE and RMSE (adj.) are in pp of scale range, the same unit as the pooled row."
field_group_table(field_by_intervention, "condition") |>
  gt() |>
  sub_missing(missing_text = "—") |>
  cols_label(condition = "Intervention")
```
As a **secondary analysis**, the pooled metrics are recomputed within two outcome classes: the eleven self-report attitude sliders, and the two behavioral outcomes (the donation and the newsletter signup). This analysis allows us to answer whether an approach that predicts stated attitudes also predicts behavior (@tbl-field-by-class).
```{r}
#| label: tbl-field-by-class
#| tbl-cap: "Secondary field summary by outcome class (placeholder data). Median across approaches of each pooled metric, computed within the eleven self-report outcomes and within the two behavioral outcomes (donation, newsletter signup), with the human replication reference in parentheses. All estimates in pp of scale range."
field_by_class <- imap_dfr(pairs_list, function(pr, sub) {
  metrics_by_group(pr |> mutate(class = unname(outcome_class[outcome])),
                   "class",
                   f = \(p) pooled_metrics(p, include_rmse = TRUE)) |>
    mutate(submission = sub)
}) |>
  pivot_longer(c(directional_pct, spearman_rho, pearson_r, pearson_adj,
                 rmse, rmse_adj),
               names_to = "metric", values_to = "value") |>
  relabel_metrics(ladder_labels)

field_group_table(field_by_class, "class") |>
  gt() |>
  sub_missing(missing_text = "—") |>
  cols_label(class = "Outcome class")
```
#### Subgroup recovery {#sec-subgroup-recovery}
This section looks at whether an approach reproduces *who* an intervention works on. Estimation, unit, and metrics are specified in [Section 2](#sec-section-2) above. The demonstration fits the interaction models on the demo outcome set (see the callout above) and pools each Tier-1 submission's interaction estimates against Human 1. In the real run, Tier-2 entries enter the same comparison through their submitted moderator cell means (see [*Three levels (tiers) of submissions*](#sec-tiers)).
```{r}
#| label: subgroup-pairs
# Human-1 interaction estimates, computed once and reused for every submission.
# The cached() keys keep their historical "amendment_" prefix (the analysis is
# unchanged); they are internal identifiers for analysis/results/*.rds, not tied
# to this file's name, so renaming the document does not require a recompute.
# The binary newsletter outcome runs through the same OLS machinery as a
# linear probability model: in the saturated condition × moderator
# specification the interaction coefficient is exactly the
# difference-in-differences of cell signup proportions — the interaction on
# the probability scale — and the HC2 robust SEs are valid for a binary
# response. It then pp-rescales (× 100) like every other outcome.
human_mod_side <- cached("amendment_human_mod_side", {
  map_dfr(outcomes_subgroup, function(out) {
    map_dfr(moderators_cat, function(mod) {
      run_moderator_model(human_data_1, outcome = out, moderator = mod,
                          compute_predicted = FALSE)$interaction_effects |>
        # se_h feeds the adjusted correlation; only the human reference side
        # is corrected (see "Adjusted correlation and RMSE").
        select(condition, moderator_level,
               estimate_h = estimate, se_h = std.error) |>
        mutate(outcome = out, moderator = mod)
    })
  })
})

build_subgroup_pairs <- function(pred_data) {
  pred_data <- align_submission_levels(pred_data)
  pred_side <- map_dfr(outcomes_subgroup, function(out) {
    map_dfr(moderators_cat, function(mod) {
      run_moderator_model(pred_data, outcome = out, moderator = mod,
                          compute_predicted = FALSE)$interaction_effects |>
        select(condition, moderator_level, estimate_l = estimate) |>
        mutate(outcome = out, moderator = mod)
    })
  })
  joined <- inner_join(human_mod_side, pred_side,
             by = c("condition", "moderator_level", "outcome", "moderator")) |>
    pp_scale_pairs()
  # Same silent-shrinkage guard as the ATE builders: every human-side
  # interaction estimate must find its counterpart in the submission's refit.
  stopifnot(nrow(joined) == nrow(human_mod_side))
  joined
}

# Tier-1 submissions plus the reference are eligible. Interaction pairs are built
# once per submission and reused by the subgroup figure and its companion table.
subgroup_inputs <- c(
  set_names(
    map(tier1_ids, ~ llm_data_teams |> filter(team == paste0("team_", .x))),
    paste0("Team ", tier1_ids)
  ),
  list("Human replication" = human_data_2)
)
subgroup_pairs_list <- cached("amendment_subgroup_pairs", {
  map(subgroup_inputs, build_subgroup_pairs)
}) |>
  relabel_submissions()
```
@fig-subgroup-headline shows the moderation analogue of the headline figure. Panel A shows the raw prediction task on the interaction estimates, and panel B the key metric per moderator, showing which kinds of heterogeneity the field can predict at all. The full signed-effect metrics, pooled, are in @tbl-field-subgroup.
```{r}
#| label: fig-subgroup-headline
#| fig-width: 11
#| fig-height: 4.2
#| fig-cap: "Subgroup recovery (placeholder data, Tier 1). (A) Predicted against human condition × moderator interaction estimates pooled across all approaches and the demo outcome set (four outcomes plus the binary newsletter signup; the registered analysis runs all outcomes), in percentage points of each outcome's scale range. Axes are centered on zero, the dashed line is the identity, and red crosses mark the human replication reference. The solid lines are the average calibration regression of human on predicted estimates (dark blue the field, red the human replication), with a corner readout of the mean field and human Pearson r (with its noise-corrected value) and calibration coefficients (β and α with 95% CIs). (B) Distribution of each approach's Pearson r on the interaction estimates, per moderator (pooled across the demo outcome set), with the field mean and its 95% CI (white diamond) per row. Red crosses mark the reference, the dotted line the null."
moderator_label_map <- c(gender = "Gender", age_band = "Age",
                         race = "Race/ethnicity", education = "Education",
                         income = "Income", party = "Party ID")

# Pairs are already in pp of scale range (pp_scale_pairs() in the builder).
subgroup_scatter_pairs <- imap_dfr(subgroup_pairs_list,
                                   ~ mutate(.x, submission = .y))
# ~37,000 pooled pairs: much lighter marks than the ATE scatter, or it reads
# as a solid blob.
p_sub_scatter <- plot_pred_scatter(
  subgroup_scatter_pairs,
  x_lab       = "Predicted interaction estimate (pp)",
  y_lab       = "Human interaction estimate (pp)",
  tag         = "A",
  point_alpha = 0.05, point_size = 0.3,
  ref_alpha   = 0.2,  ref_size   = 0.5,
  symmetric   = TRUE
)

# Mean field / human Pearson r on the interaction estimates (from the pooled
# signed-effect ladder, matching panel B), and the calibration lines + readout.
subgroup_ld <- imap_dfr(subgroup_pairs_list,
                        ~ signed_metrics(.x) |> mutate(submission = .y))
sub_field_ld <- subgroup_ld |> filter(submission != "Human replication")
sub_human_ld <- subgroup_ld |> filter(submission == "Human replication")
p_sub_scatter <- p_sub_scatter +
  calibration_overlay(subgroup_scatter_pairs,
                      r_field    = mean(sub_field_ld$pearson_r,   na.rm = TRUE),
                      radj_field = mean(sub_field_ld$pearson_adj, na.rm = TRUE),
                      r_human    = sub_human_ld$pearson_r,
                      radj_human = sub_human_ld$pearson_adj)

field_subgroup_by_mod <- imap_dfr(subgroup_pairs_list, function(pr, sub) {
  pr |>
    group_by(moderator) |>
    group_modify(~ signed_metrics(.x)) |>
    ungroup() |>
    mutate(submission = sub)
}) |>
  transmute(submission,
            value      = pearson_r,
            moderator  = factor(unname(moderator_label_map[moderator]),
                                levels = unname(moderator_label_map)),
            metric     = factor("Moderators"))
p_sub_field <- plot_metric_distribution(
  field_subgroup_by_mod, x = "moderator", mean_ci = TRUE,
  ref_lines = c("Moderators" = 0)
) + labs(tag = "B", y = "Pearson r")

(p_sub_scatter | p_sub_field) + plot_layout(widths = c(1, 1.3))
```
```{r}
#| label: tbl-field-subgroup
#| tbl-cap: "Field summary of subgroup recovery (placeholder data, Tier 1). Center and spread across approaches of each signed-effect metric on the condition × moderator interaction estimates (in pp of scale range), pooled across the demo outcome set (four outcomes plus newsletter signup; the registered analysis runs all outcomes) and six moderators (human replication reference excluded)."
field_subgroup <- imap_dfr(subgroup_pairs_list, function(pr, sub) {
  signed_metrics(pr) |>
    pivot_longer(everything(), names_to = "metric", values_to = "value") |>
    mutate(submission = sub)
}) |>
  relabel_metrics(ladder_labels[c("directional_pct", "spearman_rho",
                                  "pearson_r", "pearson_adj")])

summarise_field(field_subgroup) |>
  gt() |>
  fmt_number(columns = c(mean, median, sd, min, max), decimals = 2) |>
  cols_label(metric = "Metric", mean = "Mean", median = "Median",
             sd = "SD", min = "Min", max = "Max")
```
#### Response-shape recovery {#sec-response-shape}
This section looks at how well an approach reproduces the human response distributions. Metrics and level check are specified in [Section 3](#sec-section-3) above. @fig-distribution-headline shows the raw control-condition response densities for every continuous outcome, one facet per outcome, with the field's median variance ratio and Wasserstein-1 distance stamped next to the human replication's. The control-condition means and all four shape metrics per outcome are in @tbl-field-distribution.
```{r}
#| label: distribution-pairs
# The OVL/W1 evaluation grid is fixed to each outcome's scale range (0-100
# sliders, 0-10 donation), so every submission is scored on the identical
# grid — with the empirical default the grid would follow each submission's
# observed min/max, and the integrated areas would not be comparable across
# teams.
dist_per_outcome <- function(pred_data) {
  map_dfr(outcomes_distribution, function(out) {
    compare_distributions(human_data_1, pred_data, out, control_lab,
                          include_w1 = TRUE,
                          range = c(0, scale_range[[out]])) |>
      mutate(outcome = out,
             # the plain level check beside the shape metrics: each sample's
             # control-condition mean (mean_h = Human 1, identical for every
             # submission; mean_l = the submission's own control mean)
             mean_h = mean(filter(human_data_1,
                                  condition == control_lab)[[out]], na.rm = TRUE),
             mean_l = mean(filter(pred_data,
                                  condition == control_lab)[[out]], na.rm = TRUE))
  })
}

dist_labels <- c(mean_l = "Mean", ovl = "Overlap (OVL)", w1 = "Wasserstein-1",
                 ks_d = "KS distance", variance_ratio = "Variance ratio")

# Per-outcome shape metrics built once per submission, reused by the
# distribution figure and its companion table (cached: 29 x 12 KDE/ECDF
# passes over full respondent-level data).
dist_per_outcome_list <- cached("amendment_dist_per_outcome", {
  map(subgroup_inputs, dist_per_outcome)
}) |>
  relabel_submissions()
```
```{r}
#| label: fig-distribution-headline
#| fig-width: 11
#| fig-height: 7
#| fig-cap: "Response-shape recovery (placeholder data, Tier 1). Control-condition response densities for every continuous outcome (the eleven 0–100 sliders and the $0–10 donation, each facet on its own scale). In each facet, every Tier-1 approach is a thin line, Human 1 (the reference half) the bold line, and Human 2 (the replication half) the dashed red line. The corner stamp reports two numbers for that outcome, the variance ratio (VR, approach ÷ human, 1 = matched spread, below 1 = under-dispersion) and the Wasserstein-1 distance (W1, in scale points, 0 = identical distributions, larger = more different), for both the synthetic field (median across approaches, 'Field') and the human replication ('Human', Human 2 vs Human 1). VR captures spread, W1 captures how far the whole distribution sits from the human one in both location and shape. The full shape metrics per outcome are in the companion table."
# Per facet, stamp the field's median variance ratio and Wasserstein-1 distance
# alongside the human replication's (Human 2 vs Human 1), so each panel shows
# both spread (VR) and overall distributional distance (W1) for the synthetic
# field and the human reference.
field_dist_ann <- imap_dfr(dist_per_outcome_list,
                           ~ mutate(.x, submission = .y)) |>
  filter(submission != "Human replication") |>
  group_by(outcome) |>
  summarise(vr = median(variance_ratio, na.rm = TRUE),
            w1 = median(w1, na.rm = TRUE), .groups = "drop")

human_dist_ann <- dist_per_outcome_list[["Human replication"]] |>
  select(outcome, w1, vr = variance_ratio)

dist_ann <- left_join(field_dist_ann, human_dist_ann,
                      by = "outcome", suffix = c("_field", "_human")) |>
  mutate(label = sprintf("Field   VR %.2f   W1 %.2f\nHuman  VR %.2f   W1 %.2f",
                         vr_field, w1_field, vr_human, w1_human)) |>
  select(outcome, label)

# wrapped primary-outcome label: the full one clips its facet strip
density_labels <- outcome_label_map
density_labels["trust_multidimensional"] <- "Multidimensional trust\n(primary)"

plot_density_overlay(
  human_data_1, human_data_2,
  # Tier-1 entries only, matching the caption and the field stamps (teams 29
  # and 30 exist as individual-level placeholder data but enter as Tier 2/3).
  llm_data_teams |> filter(!team %in% c("team_29", "team_30")),
  outcomes       = outcomes_distribution,
  condition_val  = control_lab,
  outcome_labels = density_labels,
  annotations    = dist_ann,
  # free x scales: the donation facet runs 0-10 where the sliders run 0-100
  facet_scales   = "free",
  x_lab          = "Response (control condition)"
)
```
```{r}
#| label: tbl-field-distribution
#| tbl-cap: "Field summary of response levels and shapes by outcome (placeholder data, Tier 1). Human mean is the reference half's (Human 1) control-condition mean. All other columns give the median across approaches, with the human replication reference (Human 2) in parentheses: the submissions' own control-condition means as the level check, then the four shape metrics against Human 1. Ideal values are a mean matching the human one, OVL = 1, W1 = 0, KS = 0, and variance ratio = 1."
field_distribution <- imap_dfr(dist_per_outcome_list, function(d, sub) {
  d |>
    pivot_longer(c(mean_l, ovl, w1, ks_d, variance_ratio),
                 names_to = "metric", values_to = "value") |>
    mutate(submission = sub)
}) |>
  mutate(outcome = factor(unname(outcome_label_map[outcome]),
                          levels = unname(outcome_label_map))) |>
  relabel_metrics(dist_labels)

# The level target itself: Human 1's control mean per outcome (identical in
# every submission's rows, so any list element serves).
human_baseline <- dist_per_outcome_list[[1]] |>
  distinct(outcome, mean_h) |>
  mutate(outcome = factor(unname(outcome_label_map[outcome]),
                          levels = unname(outcome_label_map)))

field_group_table(field_distribution, "outcome", pct_metrics = character()) |>
  left_join(human_baseline, by = "outcome") |>
  relocate(mean_h, .after = outcome) |>
  gt() |>
  fmt_number(columns = mean_h, decimals = 2) |>
  sub_missing(missing_text = "—") |>
  cols_label(outcome = "Outcome", mean_h = "Human mean")
```
### Finding 2 — Ranking approaches (secondary) {#sec-finding-2}
Having characterized the field, we rank individual approaches along the different evaluation metrics. The leaderboard (@tbl-leaderboard) has one row per submission, and uses the neutral submission labels rather than team names (see [*Entries per team*](#sec-entries)). @fig-headline (panel B) visualizes the ranking on the key metric.
```{r}
#| label: tbl-leaderboard
#| tbl-cap: "Cross-team leaderboard (placeholder data). Pooled ATE-recovery metrics across all outcomes (every estimate in percentage points of its outcome's scale range), plus the intercept and slope of the pooled calibration regression (95% cluster-bootstrap intervals in brackets, and the noise-corrected slope where the submission's refit standard errors exist), scored against the Human 1 reference half. The Human replication row (Human 1 vs. Human 2) shows how well two human halves of this size agree. Metrics run least to most strict, left to right. Class is the disclosure-class badge (A open, B escrowed, C sealed)."
leaderboard |>
  left_join(calib_ci, by = "submission") |>
  mutate(
    alpha_ci = if_else(is.na(alpha), NA_character_,
                       sprintf("%.2f [%.2f, %.2f]", alpha, alpha_lo, alpha_hi)),
    beta_ci  = if_else(is.na(beta), NA_character_,
                       sprintf("%.2f [%.2f, %.2f]", beta, beta_lo, beta_hi))
  ) |>
  select(submission, tier, disclosure, directional_pct,
         spearman_rho, pearson_r, pearson_within, pearson_adj, rmse, rmse_adj,
         rmse_adj_at_floor, alpha_ci, beta_ci, beta_adj) |>
  gt() |>
  fmt_number(columns = c(spearman_rho, pearson_r, pearson_within, pearson_adj,
                         rmse, rmse_adj, beta_adj),
             decimals = 2) |>
  fmt_number(columns = directional_pct, decimals = 0) |>
  sub_missing(missing_text = "—") |>
  cols_hide(columns = rmse_adj_at_floor) |>
  cols_label(
    submission      = "Submission",
    tier            = "Tier",
    disclosure      = "Class",
    directional_pct = "Directional %",
    spearman_rho    = "Spearman ρ",
    pearson_r       = "Pearson r",
    pearson_within  = "Pearson r (within)",
    pearson_adj     = "Pearson r (adj.)",
    rmse            = "RMSE (pp)",
    rmse_adj        = "RMSE (adj., pp)",
    alpha_ci        = "Calib. α [95% CI]",
    beta_ci         = "Calib. β [95% CI]",
    beta_adj        = "Calib. β (adj.)"
  ) |>
  tab_footnote(
    footnote = "A predicted exact zero makes no directional claim and scores half credit, the expected score of a coin flip — the all-zero floor therefore reads 50. The all-positive row's directional % is the share of positive human ATEs, the empirical chance level; its other scores are artifacts of a constant prediction and are not shown.",
    locations = cells_body(columns = directional_pct,
                           rows = submission %in% floor_labels)
  ) |>
  tab_footnote(
    footnote = "Correlation computed within outcomes (each outcome's mean effect subtracted on both sides): message-level skill only, with no credit for knowing which outcomes are movable.",
    locations = cells_column_labels(columns = pearson_within)
  ) |>
  tab_footnote(
    footnote = "Raw slope divided by the reliability of the predicted effects (1 − mean(se²)/var), computable only where refit standard errors exist: Tier 1 and the human replication.",
    locations = cells_column_labels(columns = beta_adj)
  ) |>
  tab_footnote(
    footnote = "Errors at or below the sampling noise of the human reference estimates; the corrected value is reported as 0.",
    locations = cells_body(columns = rmse_adj,
                           rows = !is.na(rmse_adj_at_floor) & rmse_adj_at_floor)
  ) |>
  tab_style(
    style     = cell_fill(color = "#eef3f7"),
    locations = cells_body(rows = submission == "Human replication")
  ) |>
  tab_style(
    style     = cell_fill(color = "#f4f4f4"),
    locations = cells_body(rows = submission %in% c(floor_labels, ensemble_label))
  ) |>
  tab_footnote(
    footnote = "Non-competing reference row: the field's average prediction — per intervention × outcome, the mean predicted ATE across all entries — scored through the unchanged pipeline (see Wisdom of crowds under Finding 1).",
    locations = cells_body(columns = submission,
                           rows = submission == ensemble_label)
  )
```
```{r}
#| label: tbl-submission-teams
#| tbl-cap: "Which submission is by which team (placeholder data, mock teams). One row per entry, with its tier and the team's designation of the entry (one primary per team across tiers)."
submission_meta |>
  filter(submission != "Human replication") |>
  select(submission, team, tier, entry) |>
  gt() |>
  cols_label(submission = "Submission", team = "Team",
             tier = "Tier", entry = "Designation")
```
#### Cross-metric consistency {#sec-cross-metric}
The sections above report different evaluation metrics descriptively next to each other. Here, we report Spearman correlations between these metrics. High values mean the scores sort the field similarly. Low values mean no single number should be trusted alone. @tbl-metric-consistency compares the pooled ATE-recovery metrics of [Section 1](#sec-section-1) with each other.
```{r}
#| label: tbl-metric-consistency
#| tbl-cap: "Cross-metric rank consistency within Section 1 (placeholder data). Spearman correlations between the approaches' rankings on each pair of pooled ATE-recovery metrics (reference and floor rows excluded). On placeholder data all scores are noise, so consistency is expected to be near zero."
metric_cols <- names(ladder_labels)

rank_consistency <- leaderboard |>
  filter(submission != "Human replication", submission != ensemble_label,
         !submission %in% floor_labels) |>
  select(all_of(metric_cols)) |>
  cor(method = "spearman", use = "pairwise.complete.obs")

rank_consistency |>
  as_tibble(rownames = "metric") |>
  mutate(metric = unname(ladder_labels[metric])) |>
  rename_with(~ unname(ladder_labels[.x]), all_of(metric_cols)) |>
  gt() |>
  fmt_number(columns = -metric, decimals = 2) |>
  sub_missing(missing_text = "—") |>
  cols_label(metric = "")
```
@tbl-metric-consistency-sections correlates key scores across the different sections, computed on Tier-1 entries (the only tier scored on all five):
- pooled Pearson *r* ([Section 1](#sec-section-1), ATE recovery)
- $|\beta - 1|$, the distance of the pooled calibration slope from perfect scaling ([Section 1](#sec-section-1), calibration)
- the subgroup r~adj~ ([Section 2](#sec-section-2), heterogeneity recovery)
- the mean over outcomes of the absolute log variance ratio ([Section 3](#sec-section-3), dispersion)
- the demographic baseline group-mean RMSE, pooled over moderators and outcomes in percentage points of scale range ([Section 3](#sec-section-3), baseline levels)
Error scores are sign-flipped so that higher is better everywhere. Low correlations here would mean real dissociations. For example, an approach can rank the effects right yet mis-scale them, or recover every ATE while distorting the spread of responses.
```{r}
#| label: tbl-metric-consistency-sections
#| tbl-cap: "Cross-section rank consistency (placeholder data, Tier 1). Spearman correlations between the approaches' rankings on one representative score per question: pooled Pearson r (S1, ATE recovery), |β − 1| (S1, calibration), subgroup r adj. (S2, heterogeneity), mean |log variance ratio| over outcomes (S3, dispersion), and demographic baseline group-mean RMSE in pp of scale range, pooled over moderators and outcomes (S3, level calibration). Error-type scores are sign-flipped so that higher is better everywhere, and a positive correlation then always reads as agreement. On placeholder data all scores are noise, so consistency is expected to be near zero."
# One score per question per Tier-1 entry. The baseline RMSE has no
# per-submission object elsewhere in the document, so it is computed here:
# per moderator and outcome, the RMSE of the control-condition group means
# (converted to pp of scale range), averaged over the six moderators and all
# outcomes. Cached: 29 x 13 x 6 group-mean passes over respondent-level data.
baseline_rmse_pp <- cached("amendment_baseline_rmse", {
  imap_dfr(subgroup_inputs, function(dat, sub) {
    map_dfr(outcomes_pooled, function(out) {
      compare_demographic_baselines(human_data_1, dat, out, moderators_cat) |>
        mutate(rmse_pp = rmse * 100 / scale_range[[out]])
    }) |>
      summarise(baseline_rmse = mean(rmse_pp, na.rm = TRUE)) |>
      mutate(submission = sub)
  })
}) |>
  relabel_submission_col()

section_score_labels <- c(
  pooled_r       = "Pooled r (S1)",
  calib_dist     = "|β − 1| (S1)",
  subgroup_radj  = "Subgroup r adj. (S2)",
  dispersion     = "|log VR| (S3)",
  baseline_rmse  = "Baseline RMSE (S3)"
)

section_scores <- leaderboard |>
  filter(tier == "1") |>
  transmute(submission,
            pooled_r   = pearson_r,
            calib_dist = -abs(beta - 1)) |>
  left_join(subgroup_ld |> transmute(submission, subgroup_radj = pearson_adj),
            by = "submission") |>
  left_join(imap_dfr(dist_per_outcome_list,
                     ~ tibble(submission = .y,
                              dispersion = -mean(abs(log(.x$variance_ratio)),
                                                 na.rm = TRUE))),
            by = "submission") |>
  left_join(baseline_rmse_pp |>
              transmute(submission, baseline_rmse = -baseline_rmse),
            by = "submission")

section_scores |>
  select(-submission) |>
  cor(method = "spearman", use = "pairwise.complete.obs") |>
  as_tibble(rownames = "score") |>
  mutate(score = unname(section_score_labels[score])) |>
  rename_with(~ unname(section_score_labels[.x]), -score) |>
  gt() |>
  fmt_number(columns = -score, decimals = 2) |>
  sub_missing(missing_text = "—") |>
  cols_label(score = "")
```
### Primaries-only robustness {#sec-primaries-only}
A team with three entries contributes three scores to the field summary where a single-entry team contributes one, and entries from the same team are not independent. As registered under [*Entries per team*](#sec-entries), we therefore recompute the field summary on primary entries only, one per team. Little difference between the two summaries shows that the multi-entry teams do not drive the field's results.
```{r}
#| label: tbl-field-primaries
#| tbl-cap: "Primaries-only robustness (placeholder data). The field summary of @tbl-field-summary recomputed on primary entries only (one per team), next to the all-entries values. On placeholder data every entry is a noise resample of the same dataset, so the two versions differ only in which resamples enter."
primary_subs <- submission_meta |>
  filter(entry == "primary") |>
  pull(submission)

field_primaries <- leaderboard |>
  filter(submission %in% primary_subs) |>
  select(submission, all_of(names(ladder_labels))) |>
  pivot_longer(-submission, names_to = "metric", values_to = "value") |>
  relabel_metrics(ladder_labels)

left_join(
  summarise_field(field_pooled) |>
    select(metric, mean_all = mean, sd_all = sd),
  summarise_field(field_primaries) |>
    select(metric, mean_primary = mean, sd_primary = sd),
  by = "metric"
) |>
  gt() |>
  fmt_number(columns = -metric, decimals = 2) |>
  sub_missing(missing_text = "—") |>
  tab_spanner(label = "All entries", columns = c(mean_all, sd_all)) |>
  tab_spanner(label = "Primary entries only",
              columns = c(mean_primary, sd_primary)) |>
  cols_label(metric = "Metric", mean_all = "Mean", sd_all = "SD",
             mean_primary = "Mean", sd_primary = "SD")
```
### Finding 3 — What distinguishes the approaches? {#sec-finding-3}
The goal of this benchmark is not only to test how well synthetic sampling approaches human participants' responses, but also to systematically report on how the different approaches are built. We will compile a catalogue from the benchmark's method-registration: one row per submission, with its design features coded from the free-text registration form into comparable categories, such as model family, open- vs. closed-weight, persona source, administration protocol (one item per call, blocks, whole survey, or a direct effect forecast), fine-tuning, in-context use of prior data, decoding settings, and computational cost (registration items B, D, E, F, and K in the [call for participation](index.html#registration-form)).
@tbl-catalogue-example illustrates what this catalogue table could look like. The exact coding scheme can only be finalized once we have received the submissions. The catalogue is therefore descriptive documentation rather than a registered analysis.
```{r}
#| label: tbl-catalogue-example
#| tbl-cap: "Example structure of the design-space catalogue (invented rows for illustration — these are not real submissions). One row per submission, features coded from the free-text method-registration forms into comparable categories."
tribble(
  ~submission, ~`Model family`, ~Weights, ~`Persona source`,
  ~Administration, ~`Fine-tuning`, ~`In-context data`, ~Decoding, ~`Cost (USD)`,
  "submission_1_a", "GPT-family", "Closed",
  "Census-calibrated synthetic profiles", "One item per call", "None",
  "None", "Default temperature", "310",
  "submission_2",   "Llama-family", "Open",
  "Survey-respondent personas (GSS)", "Whole survey per call",
  "LoRA on survey corpora", "Published megastudy effects",
  "Log-probability averaging", "1,150",
  "submission_3",   "Mixed (two models)", "Both",
  "No personas (direct effect forecast)", "Direct effect forecast", "None",
  "Literature retrieval", "Greedy", "40",
  "…", "…", "…", "…", "…", "…", "…", "…", "…"
) |>
  gt() |>
  cols_label(submission = "Submission")
```
With the catalogue in place, we will relate design features to performance descriptively: per feature, the distribution of the entries' pooled Pearson *r* (the Finding-1 key metric) across its categories, restricted to features where each category holds at least three submissions. We are aware that any analysis relating a specific feature to a prediction outcome is confounded by all sorts of other features that differ between approaches, and they should not be taken as causal claims, but observations that could be investigated properly by future studies.
### Robustness of the scoring pipeline {#sec-pipeline-robustness}
The scoring pipeline has researcher degrees of freedom of its own, chiefly the preregistered random seed that splits the human sample into Human 1 and Human 2 [@cumminsThreatAnalyticFlexibility2025b]. As a **resplit sensitivity check**, we redraw the half-split many times (resplit $i$ uses seed $1000 + i$, with `n_resplit_real = 200` for the real-data run and `n_resplit_demo = 50` in this placeholder render) and recompute the human replication reference on each. The spread of the reference's metrics across resplits is reported alongside the values under the preregistered seed. A narrow spread shows that the split seed is not driving the results. The demonstration below recomputes the reference only. When the real submissions are in, the check goes one step further: each resplit yields a different Human 1, every submission is rescored against it, and each entry ends up with one score per resplit. We then report whether the field summary and the leaderboard order stay stable across these alternative versions of the analysis.
```{r}
#| label: tbl-resplit
#| tbl-cap: "Split-seed sensitivity of the human replication reference (placeholder data, 50 resplits; the real-data run uses the preregistered 200). Distribution of each pooled ATE-recovery metric for the Human 1 vs. Human 2 comparison across the alternative random half-splits, next to the value under the preregistered seed. On placeholder data the reference is also noise-level, so the check demonstrates the code, not a substantive reference value. The resplits are drawn from the same sample and so are mutually dependent. The spread quantifies split-conditional variability, not independent replications."
resplit_ceiling <- cached("amendment_resplit_ceiling", {
  all_ids <- unique(human_data$id)

  map_dfr(seq_len(n_resplit_demo), function(i) {
    set.seed(1000 + i)
    ids_i <- sample(all_ids, size = floor(length(all_ids) / 2))
    h1_i  <- human_data |> filter(id %in% ids_i)
    h2_i  <- human_data |> filter(!id %in% ids_i)

    # Same 13-outcome pipeline as the leaderboard: ate_side() covers the
    # continuous outcomes, the donation, and the binary newsletter signup;
    # pp_scale_pairs() puts every estimate in pp of scale range.
    inner_join(
      ate_side(h1_i) |>
        rename(estimate_h = estimate, se_h = se),
      ate_side(h2_i) |>
        select(condition, outcome, estimate_l = estimate),
      by = c("condition", "outcome")
    ) |>
      pp_scale_pairs() |>
      assert_full_grid() |>
      pooled_metrics(include_rmse = TRUE) |>
      mutate(resplit = i)
  })
})

resplit_ceiling |>
  pivot_longer(-resplit, names_to = "metric", values_to = "value") |>
  filter(metric %in% names(ladder_labels)) |>
  group_by(metric) |>
  summarise(mean = mean(value, na.rm = TRUE), sd = sd(value, na.rm = TRUE),
            min = min(value, na.rm = TRUE),  max = max(value, na.rm = TRUE),
            n_defined = sum(!is.na(value)), .groups = "drop") |>
  left_join(
    pairs_list[["Human replication"]] |>
      pooled_metrics(include_rmse = TRUE) |>
      pivot_longer(everything(), names_to = "metric",
                   values_to = "preregistered_seed"),
    by = "metric"
  ) |>
  mutate(metric = factor(unname(ladder_labels[metric]),
                         levels = unname(ladder_labels))) |>
  arrange(metric) |>
  gt() |>
  fmt_number(columns = c(mean, sd, min, max, preregistered_seed), decimals = 2) |>
  sub_missing(missing_text = "—") |>
  cols_label(metric = "Metric", mean = "Mean", sd = "SD", min = "Min",
             max = "Max", n_defined = "N defined",
             preregistered_seed = "Preregistered seed")
```
When real submissions arrive, the findings are recomputed by replacing the placeholder datasets with the submitted prediction files routed through their tier's builder (`build_pairs_t1()` / `build_pairs_t2()` / `build_pairs_t3()`). The subgroup and distribution figures are produced for the tiers eligible for them, alongside the demographic-baseline and stereotyping diagnostics of [Section 3](#sec-section-3), including the demographic parity gap (`demographic_parity_gap()`).